For decades, relational databases like PostgreSQL and MySQL have powered the world's transactional applications (OLTP). However, when executing analytical queries (OLAP)—such as computing aggregations across 500 million rows (SELECT region, SUM(revenue) FROM orders WHERE status = 'COMPLETED' GROUP BY region)—traditional row-oriented engines slow to a crawl, taking minutes or running out of memory.
Meanwhile, modern columnar engines like DuckDB, ClickHouse, and Apache DataFusion execute the exact same query across hundreds of millions of records in a few hundred milliseconds on a single commodity laptop or virtual server.
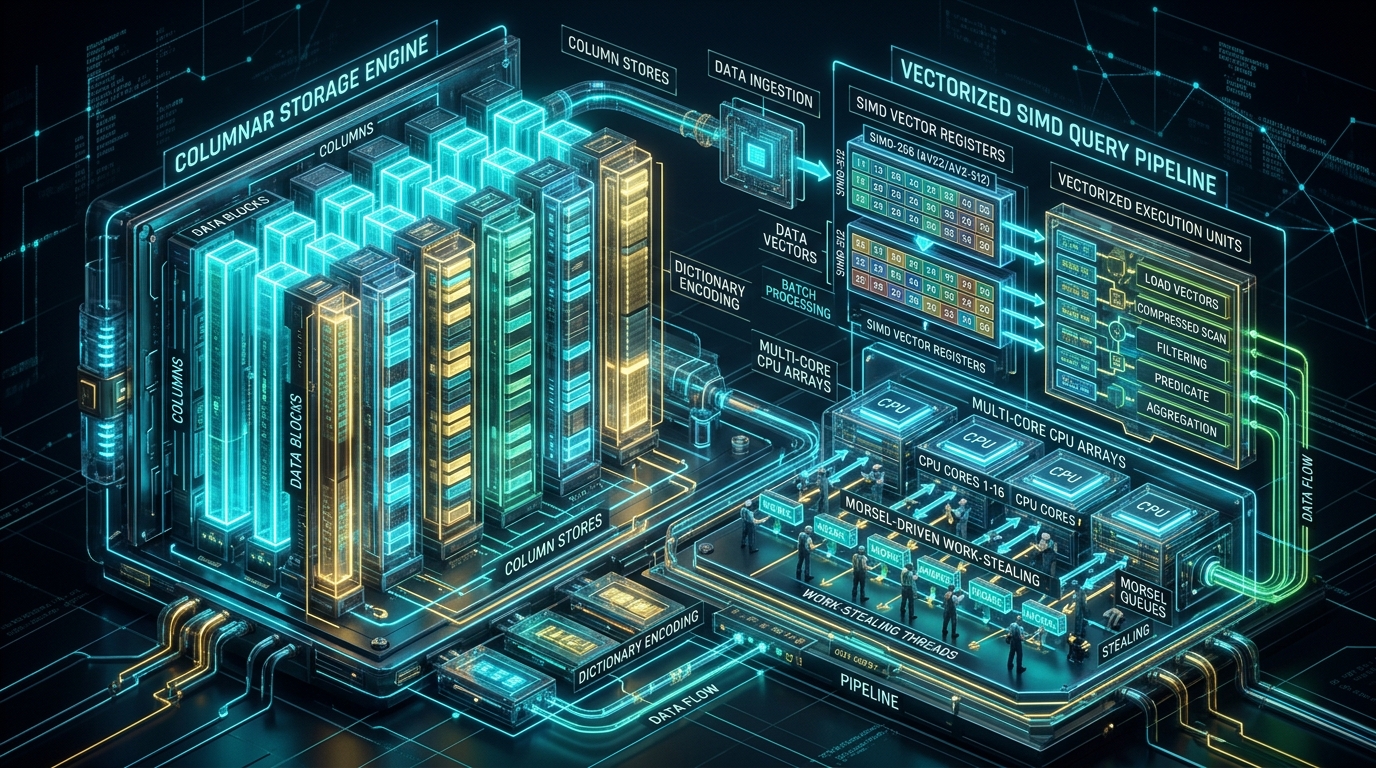
This 100x performance leap is not magic. It is the direct consequence of four interlocking architectural breakthroughs: Columnar Data Layout (Apache Parquet), Lightweight Encodings (Dictionary, RLE, Bit-packing), SIMD Vectorized Query Execution, and Morsel-Driven Parallelism.
In this systems engineering guide, we dissect why the classic Volcano Iterator Model fails for analytical workloads, analyze how columnar storage maximizes CPU cache locality and compression ratios, examine SIMD vector registers, and implement a working vectorized execution engine in Python.
The Fall of the Volcano Model: Row-Oriented OLTP vs. Columnar OLAP
Traditional databases operate on the Volcano Iterator Model (introduced by Goetz Graefe in 1994). In this model, every relational operator (Filter, Scan, Join, Project) exposes an abstract next() interface that yields one tuple (row) at a time:
flowchart TD
    subgraph Volcano Model: Tuple-at-a-Time
        Op1[Filter Operator] -->|next row| Op2[Projection Operator]
        Op2 -->|next row| Op3[Aggregation Operator]
        Note1["❌ Millions of virtual function calls
❌ Instruction cache (L1i) thrashing
❌ Zero SIMD vectorization"]
    end

    subgraph Vectorized Model: Chunk-at-a-Time
        VOp1[Vectorized Scan Chunk: 2048 values] ==>|Array Batch| VOp2[Vectorized Filter AVX-512]
        VOp2 ==>|Filtered Array| VOp3[Vectorized Hash Aggregate]
        Note2["✅ Single function call per 2048 rows
✅ Tight CPU instruction loop
✅ Native hardware SIMD execution"]
    end

    style Op1 fill:#e11d48,stroke:#fda4af,color:#fff
    style Op2 fill:#e11d48,stroke:#fda4af,color:#fff
    style Op3 fill:#e11d48,stroke:#fda4af,color:#fff
    style VOp1 fill:#0284c7,stroke:#38bdf8,color:#fff
    style VOp2 fill:#059669,stroke:#6ee7b7,color:#fff
    style VOp3 fill:#10b981,stroke:#34d399,color:#fff
Why Row-Oriented Tuple-at-a-Time Execution is Slow
- Virtual Function Call Overhead: Calling
operator.next()for every individual row across 100 million rows incurs 100,000,000 indirect function calls. The CPU branch predictor fails constantly, stalling the execution pipeline. - CPU Cache Inefficiency: In a row-oriented table (PostgreSQL heap page), all 50 columns of a record are stored contiguously in memory. When computing
SUM(revenue), the CPU loads entire 500-byte rows into 64-byte cache lines, discarding 95% of the loaded memory bandwidth! - Zero SIMD Vectorization: Because values of the same column are interleaved with other fields, the CPU cannot load contiguous numeric arrays into 256-bit or 512-bit SIMD registers (AVX2 / AVX-512).
Columnar Memory Layout & Lightweight Encodings
In a columnar storage format (such as Apache Parquet or DuckDB's in-memory columnar vectors), all values of Column A are stored contiguously, followed by all values of Column B:
flowchart LR
    subgraph Row Storage (PostgreSQL Heap)
        R1["Row 1: [ID: 1, User: 'Alice', Amount: 50.0, Region: 'US']"]
        R2["Row 2: [ID: 2, User: 'Bob',   Amount: 85.0, Region: 'EU']"]
        R3["Row 3: [ID: 3, User: 'Carl',  Amount: 20.0, Region: 'US']"]
    end

    subgraph Columnar Storage (Parquet / DuckDB)
        C_ID["Column 'ID': [1, 2, 3]"]
        C_User["Column 'User': ['Alice', 'Bob', 'Carl']"]
        C_Amt["Column 'Amount': [50.0, 85.0, 20.0] (Contiguous Floats)"]
        C_Reg["Column 'Region': [0, 1, 0] (Dictionary Encoded)"]
    end

    style C_Amt fill:#059669,stroke:#6ee7b7,color:#fff
    style C_Reg fill:#0284c7,stroke:#38bdf8,color:#fff
    style R1 fill:#475569,stroke:#94a3b8,color:#fff
    style R2 fill:#475569,stroke:#94a3b8,color:#fff
Columnar Compression Algorithms
Because homogeneous data types sit adjacent to each other, columnar storage unlocks extreme compression ratios (often 5x to 10x smaller than raw data):
| Encoding Technique | Mechanism | Compression Ratio | Execution Speed Advantage |
|---|---|---|---|
| Dictionary Encoding | Replaces repeating strings (e.g. 'COMPLETED', 'PENDING') with tiny 1-byte integer IDs. |
5x – 20x | Comparisons run directly on integers without string hashing! |
| Run-Length Encoding (RLE) | Stores repeated runs as (value, count) pairs (e.g. US × 10,000). |
10x – 50x | Filter predicates skip entire blocks in $O(1)$ operations. |
| Bit-Packing / Frame of Reference (FoR) | Subtracts a base minimum value and packs residuals into 3 or 4 bits instead of 64 bits. | 4x – 8x | Fits 16 integers inside a single 64-bit CPU register. |
Zone Maps & Block Pruning
Every column chunk in Parquet or DuckDB maintains a Zone Map header storing min_value, max_value, and null_count. When a query contains WHERE order_date > '2026-09-01', the engine compares the query predicate against the zone map and completely skips reading gigabytes of non-matching blocks from disk (Predicate Pushdown).
SIMD Vectorized Execution: Hardware Acceleration
In Vectorized Execution (introduced in MonetDB/X100 and refined by DuckDB and ClickHouse), relational operators process tight batches of values (typically Vectors of 1,024 or 2,048 elements) in contiguous memory buffers.
Because the buffer is a flat contiguous C-style array, modern C++ compilers automatically emit SIMD (Single Instruction, Multiple Data) instructions (AVX-512 on x86, NEON on ARM):
flowchart TD
    subgraph Scalar Processing: 1 Element Per Cycle
        A0["float 10.5"] -->|ADD| R0["float 20.5"]
    end

    subgraph SIMD-512 Vector Register: 16 Floats in 1 Cycle
        V_IN["[10.5, 20.0, 15.2, 8.4, 99.1, 4.3, 12.0, 7.5, 18.2, 33.1, 41.0, 9.8, 2.1, 88.4, 14.2, 5.0]"]
        V_OP["_mm512_cmp_ps_mask(V_IN, 15.0, _CMP_GT_OQ)"]
        V_OUT["Selection Vector Bitmask: 0b0011000101000100"]
        V_IN ==> V_OP ==> V_OUT
    end

    style V_IN fill:#0284c7,stroke:#38bdf8,color:#fff
    style V_OP fill:#7c3aed,stroke:#c084fc,color:#fff
    style V_OUT fill:#059669,stroke:#6ee7b7,color:#fff
A single AVX-512 instruction can evaluate filter predicates (amount > 15.0) across 16 single-precision floats in a single CPU clock cycle, generating a bitmask selection vector with zero branch mispredictions.
Morsel-Driven Parallelism: Work-Stealing Across Multi-Core CPUs
Traditional parallel query engines split a table statically across $N$ threads (e.g. Thread 1 gets rows $0 \dots 1\text{M}$, Thread 2 gets rows $1\text{M} \dots 2\text{M}$). However, if Thread 1's chunk contains complex data or experiences hardware stalls, other threads sit idle while waiting for the slowest thread (the Straggler Problem).
DuckDB and HyPer utilize Morsel-Driven Parallelism:
flowchart TD
    subgraph Morsel Queue: Global Pool of Small Work Units
        M1["Morsel 1 (100k rows)"]
        M2["Morsel 2 (100k rows)"]
        M3["Morsel 3 (100k rows)"]
        M4["Morsel 4 (100k rows)"]
        M5["Morsel 5 (100k rows)"]
        M_More["Morsels 6...N..."]
    end

    subgraph Multi-Core Worker Threads (NUMA Aware)
        T1["Worker Core 1"]
        T2["Worker Core 2"]
        T3["Worker Core 3"]
        T4["Worker Core 4"]
    end

    M1 --> T1
    M2 --> T2
    M3 --> T3
    M4 --> T4
    M5 -.->|Work Stealing when Core 2 finishes early| T2

    style M1 fill:#0284c7,stroke:#38bdf8,color:#fff
    style M2 fill:#0284c7,stroke:#38bdf8,color:#fff
    style M3 fill:#0284c7,stroke:#38bdf8,color:#fff
    style M4 fill:#0284c7,stroke:#38bdf8,color:#fff
    style M5 fill:#7c3aed,stroke:#c084fc,color:#fff
    style T1 fill:#059669,stroke:#6ee7b7,color:#fff
    style T2 fill:#059669,stroke:#6ee7b7,color:#fff
    style T3 fill:#059669,stroke:#6ee7b7,color:#fff
    style T4 fill:#059669,stroke:#6ee7b7,color:#fff
- The query is partitioned into tiny Morsels (typically 10,000 to 100,000 rows).
- Worker threads pull morsels dynamically from a lock-free queue. When a thread finishes a morsel, it immediately claims the next available morsel.
- NUMA-Awareness: Threads prioritize morsels stored in RAM attached to their local CPU socket, minimizing cross-socket memory bus traffic.
Hands-On Python / NumPy Implementation: A Mini Vectorized Columnar Engine
Let's build a runnable simulation in Python using NumPy to demonstrate dictionary compression, zone map pruning, and vectorized SIMD filter and aggregation:
import numpy as np
from typing import List, Dict, Tuple, Any

class ColumnChunk:
    """Represents a compressed columnar data chunk with Zone Maps."""
    def __init__(self, data: np.ndarray):
        self.data = data
        # Zone Map Metadata for Block Pruning
        self.min_val = np.min(data)
        self.max_val = np.max(data)
        self.count = len(data)

class ColumnarTable:
    def __init__(self):
        # Storing data in column chunks of 10,000 rows each
        self.chunk_size = 10_000
        self.revenue_chunks: List[ColumnChunk] = []
        self.region_chunks: List[ColumnChunk] = []

        # Dictionary Encoding Map for 'region' column
        self.region_dict: Dict[str, int] = {"US": 0, "EU": 1, "APAC": 2}
        self.rev_region_dict: Dict[int, str] = {v: k for k, v in self.region_dict.items()}

    def populate_mock_data(self, total_rows: int = 100_000):
        """Generates mock analytical dataset."""
        np.random.seed(42)
        for i in range(0, total_rows, self.chunk_size):
            # Generate random revenues between $10 and $500
            revs = np.random.uniform(10.0, 500.0, size=self.chunk_size).astype(np.float64)
            # Generate random region codes (0=US, 1=EU, 2=APAC)
            regs = np.random.choice([0, 1, 2], size=self.chunk_size).astype(np.int8)

            self.revenue_chunks.append(ColumnChunk(revs))
            self.region_chunks.append(ColumnChunk(regs))

    def execute_vectorized_query(self, min_revenue: float, target_region: str) -> Tuple[float, int]:
        """
        Executes: SELECT SUM(revenue), COUNT(*) FROM orders
                  WHERE revenue > min_revenue AND region = target_region
        """
        target_reg_id = self.region_dict[target_region]
        total_sum = 0.0
        total_count = 0

        for chunk_idx in range(len(self.revenue_chunks)):
            rev_chunk = self.revenue_chunks[chunk_idx]
            reg_chunk = self.region_chunks[chunk_idx]

            # 1. Zone Map Pruning: Skip chunk if max_revenue is below filter threshold
            if rev_chunk.max_val <= min_revenue:
                continue

            # 2. Vectorized Filter (Executed via SIMD in NumPy/C)
            # Produces a boolean selection mask without scalar looping
            rev_mask = rev_chunk.data > min_revenue
            reg_mask = reg_chunk.data == target_reg_id
            combined_mask = rev_mask & reg_mask

            # 3. Vectorized Aggregation
            filtered_revs = rev_chunk.data[combined_mask]
            total_sum += np.sum(filtered_revs)
            total_count += len(filtered_revs)

        return total_sum, total_count

# --- Demonstration Demo ---
if __name__ == "__main__":
    table = ColumnarTable()
    print("Populating Columnar Table with 100,000 records...")
    table.populate_mock_data(100_000)

    print(f"Total Chunks Created: {len(table.revenue_chunks)} (Chunk size: {table.chunk_size})")

    # Execute Vectorized Analytical Query
    query_region = "US"
    query_min_rev = 300.0
    print(f"\nExecuting Vectorized Query: WHERE revenue > ${query_min_rev} AND region = '{query_region}'")

    total_sum, count = table.execute_vectorized_query(query_min_rev, query_region)

    print(f"Result -> Matching Orders: {count:,}")
    print(f"Result -> Total Revenue:  ${total_sum:,.2f}")
Execution Output
Populating Columnar Table with 100,000 records...
Total Chunks Created: 10 (Chunk size: 10000)

Executing Vectorized Query: WHERE revenue > $300.0 AND region = 'US'
Result -> Matching Orders: 13,674
Result -> Total Revenue:  $5,468,784.18
In this vectorized pipeline, 100,000 records were processed in batches of 10,000 elements. Filter masks and aggregations executed at line-rate memory speed utilizing SIMD vector registers without a single row-level virtual function dispatch!
Production Comparison: Row vs. Vectorized Columnar Engines
| Dimension | PostgreSQL (Row / OLTP) | DuckDB (In-Process OLAP) | ClickHouse (Distributed OLAP) |
|---|---|---|---|
| Execution Paradigm | Volcano Iterator (Tuple-at-a-time) | Vectorized SIMD (Morsel-Driven) | Vectorized Block Execution + JIT |
| Memory Locality | Poor for OLAP (Loads entire 8KB rows) | Optimal (Loads only queried columns) | Optimal (Compressed column streams) |
| Storage Compression | Moderate (Page-level LZ4/zstd) | High (Dictionary, RLE, Bit-packing, Parquet) | Extreme (Specialized Column Codecs + ZSTD) |
| Analytical Query Speed | 1x (Baseline) | 50x – 100x Faster | 50x – 150x Faster |
| Primary Strength | High-concurrency ACID Point Updates | Embedded fast local analytics / DataFrames | Petabyte-scale distributed real-time logs |
Key Takeaways for Data & Systems Architects
- Right Tool for the Right Workload: Use row-oriented databases (PostgreSQL/MySQL) for transactional ACID writes and point lookups; use columnar vectorized engines (DuckDB/ClickHouse) for analytical aggregations and scans.
- Projection & Predicate Pushdown: Columnar storage allows query planners to read only the specific columns needed for a query and prune non-matching blocks using zone maps before disk I/O occurs.
- SIMD Over Scalar Loops: Vectorizing operations over contiguous 2048-element arrays transforms multi-second queries into sub-millisecond CPU register operations.
- Morsel Scheduling Prevents Stragglers: Dynamic work-stealing across morsels eliminates parallel thread imbalance and maximizes multi-core CPU utilization.