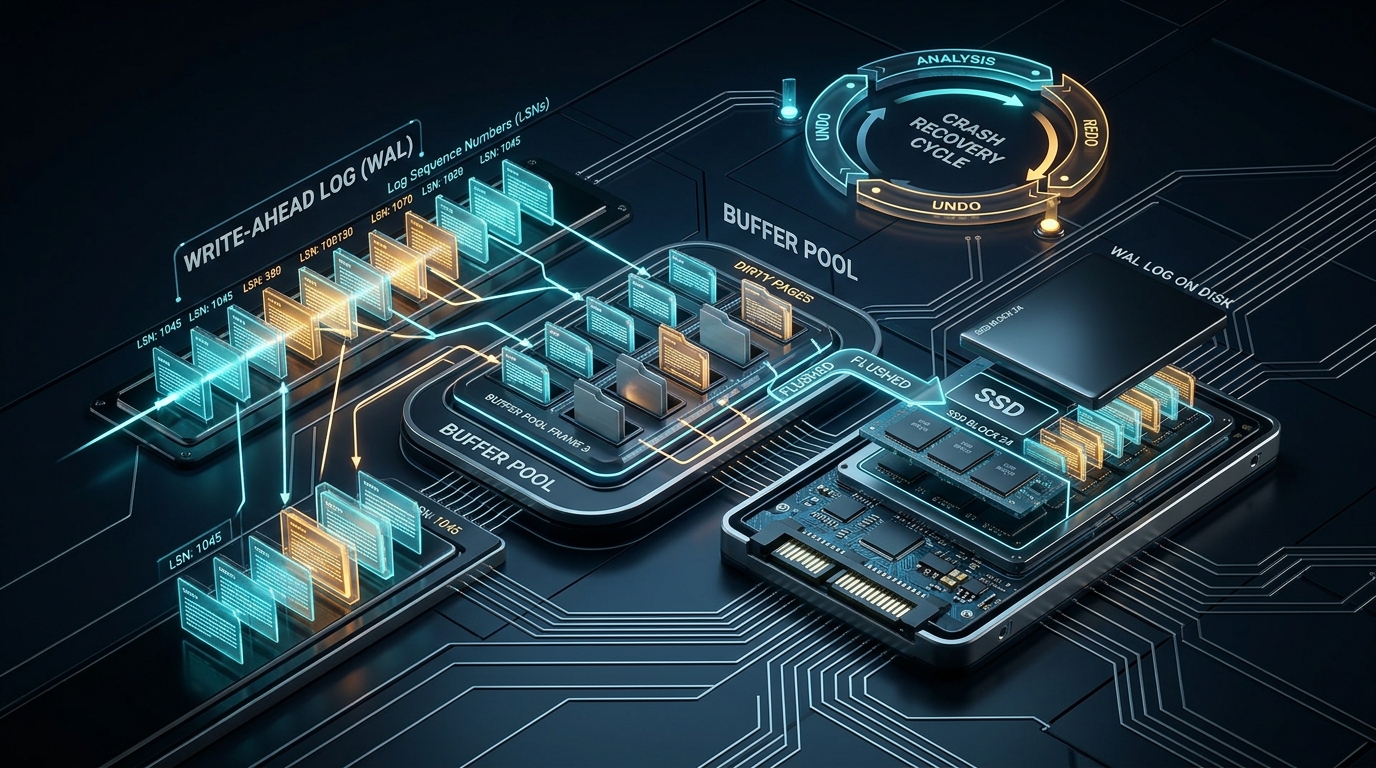
Every relational database system—from PostgreSQL and MySQL (InnoDB) to SQLite and enterprise distributed engines—makes a fundamental promise: once a transaction issues a COMMIT, its changes are permanent, even if the server suffers an abrupt power loss or operating system kernel panic milliseconds later.
Yet, flushing every modified 8KB or 16KB data page to disk synchronously upon every commit would cripple database throughput with random I/O stalls. Conversely, keeping all writes in volatile RAM risks catastrophic data loss during an unexpected crash.
The solution to this dilemma is Write-Ahead Logging (WAL) governed by the ARIES (Algorithms for Recovery and Isolation Exploiting Semantics) protocol. Invented by Dr. C. Mohan at IBM Research, ARIES is widely considered one of the most brilliant and enduring algorithmic achievements in computer science.
In this systems engineering guide, we dissect the buffer pool policy matrix (Steal/No-Force), analyze Log Sequence Numbers (LSNs), explore Fuzzy Checkpointing, walk through the three phases of crash recovery (Analysis, Redo, Undo), and implement an ARIES crash recovery engine in Python.
The Buffer Pool Policy Matrix: Steal vs. Force
To understand why recovery algorithms are necessary, consider how a database manages data in volatile RAM (the Buffer Pool) versus persistent storage (Disks / SSDs):
quadrantChart
    title Database Buffer Pool Management Policies
    x-axis "NO-STEAL (RAM holds all uncommitted)" --> "STEAL (Flushes dirty uncommitted pages)"
    y-axis "FORCE (Synchronous page flush at commit)" --> "NO-FORCE (Async page flush / WAL only)"
    quadrant-1 "STEAL + NO-FORCE: Maximum Performance (Requires UNDO + REDO in ARIES)"
    quadrant-2 "NO-STEAL + NO-FORCE: Moderate (Requires REDO only)"
    quadrant-3 "NO-STEAL + FORCE: Simplest (No UNDO, No REDO, Slowest Throughput)"
    quadrant-4 "STEAL + FORCE: Requires UNDO only (Impractical)"
The Four Policy Dimensions
- STEAL vs. NO-STEAL (Atomicity Dimension):
- STEAL (Used by modern engines): If the buffer pool runs out of memory frames, the buffer manager is permitted to "steal" a frame by writing an uncommitted transaction's dirty page to disk. This requires an UNDO logging mechanism during crash recovery to roll back uncommitted changes.
- NO-STEAL: Uncommitted pages are never written to disk. If a transaction modifies 20GB of data on a server with 8GB RAM, the database crashes with an out-of-memory error.
- FORCE vs. NO-FORCE (Durability Dimension):
- FORCE: Before acknowledging
COMMITto the client, the engine must synchronously write all modified data pages to disk. This causes severe disk thrashing due to random writes. - NO-FORCE (Used by modern engines): Upon
COMMIT, the engine only ensures that a small, compact sequential WAL record is safely synced (fsync) to disk. Modified data pages remain dirty in RAM and are flushed lazily in the background. This requires a REDO logging mechanism during crash recovery.
- FORCE: Before acknowledging
💡 The Modern Standard: STEAL + NO-FORCE
All high-performance database engines (PostgreSQL, MySQL InnoDB, SQL Server, Oracle) operate under the STEAL + NO-FORCE policy. This delivers maximum throughput and memory efficiency, but places the entire burden of correctness onto the Write-Ahead Log (WAL) and crash recovery algorithm.
The Write-Ahead Logging (WAL) Protocol & LSN Invariants
The cardinal rule of database durability is the Write-Ahead Logging Rule:
The WAL Invariant: Any log record describing a modification to a data page MUST be flushed to non-volatile storage (disk) BEFORE the dirty data page itself is allowed to be written to disk.
Log Sequence Numbers (LSNs)
To coordinate the state of memory, disk pages, and the append-only log file, ARIES assigns every log record a monotonically increasing 64-bit integer called a Log Sequence Number (LSN):
| LSN Identifier | Location | Purpose |
|---|---|---|
| PageLSN | Header of every 8KB Data Page | Records the LSN of the most recent log record that modified this page. |
| FlushedLSN | In-Memory Engine State | The highest LSN currently safely written and fsynced to disk. |
| PrevLSN | Inside every WAL Log Record | Points to the previous log record written by the same transaction (forms a backward linked list). |
| recLSN | In-Memory Dirty Page Table (DPT) | The oldest LSN that made a clean page dirty in RAM since it was last flushed. |
Whenever the buffer pool manager wants to write a dirty page to disk, it checks the invariant:
assert(page.PageLSN <= FlushedLSN)
If PageLSN > FlushedLSN, the database halts the page write, flushes the WAL log up to page.PageLSN, and only then writes the data page to disk.
Fuzzy Checkpointing: Non-Blocking Snapshots
Without checkpoints, recovering from a crash would require scanning the WAL log from the very beginning of the database's creation. However, stopping all user transactions to flush every dirty page to disk (a synchronous static checkpoint) causes catastrophic latency spikes.
ARIES introduces Fuzzy Checkpointing, which executes concurrently without blocking read or write transactions:
sequenceDiagram
    autonumber
    participant Checkpointer
    participant WAL Log
    participant Buffer Pool (RAM)

    Checkpointer->>WAL Log: Write CHECKPOINT_BEGIN record
    Checkpointer->>Buffer Pool (RAM): Snapshot Transaction Table (Active Txns + LastLSN)
    Checkpointer->>Buffer Pool (RAM): Snapshot Dirty Page Table (Dirty Pages + recLSN)
    Checkpointer->>WAL Log: Write CHECKPOINT_END record (with snapshots)
    Checkpointer->>Disk: Update Master Record pointer to CHECKPOINT_BEGIN LSN
Because the checkpoint only records the metadata state (active transactions and dirty page lists) rather than flushing gigabytes of data pages, it completes in a few milliseconds with zero transaction stalling.
The Three Phases of ARIES Crash Recovery
When the database restarts following an abrupt power outage or kernel crash, ARIES executes three sequential phases:
flowchart LR
    Crash[System Crash Occurs] --> P1[Phase 1: ANALYSIS
Scans Forward from Checkpoint]
    P1 --> P2[Phase 2: REDO (Repeat History)
Scans Forward from Min recLSN]
    P2 --> P3[Phase 3: UNDO
Scans Backward, Rolls Back Losers via CLRs]
    P3 --> Ready[Database Ready for Traffic]

    style Crash fill:#e11d48,stroke:#fda4af,color:#fff
    style P1 fill:#0284c7,stroke:#38bdf8,color:#fff
    style P2 fill:#7c3aed,stroke:#c084fc,color:#fff
    style P3 fill:#059669,stroke:#6ee7b7,color:#fff
    style Ready fill:#10b981,stroke:#34d399,color:#fff
Phase 1: The Analysis Phase
- Scans forward from the last
CHECKPOINT_BEGINto the end of the log. - Reconstructs the Transaction Table (TT) and Dirty Page Table (DPT).
- Identifies the set of "Loser Transactions": transactions that were active when the system crashed and never wrote a
COMMITorABORTrecord. - Determines the smallest
recLSNin the DPT, which marks the starting point for the Redo phase.
Phase 2: The Redo Phase ("Repeating History")
- Scans forward from the smallest
recLSNall the way to the end of the log. - Replays every single logged action, including changes made by loser transactions and operations that were later aborted.
- Redo Optimization: For each update log record, it checks:
- Is the target page in the Dirty Page Table? If not, the page was flushed to disk before the crash; skip redo.
- If in DPT and
recLSN <= record.LSN, read the page from disk. Ifpage.PageLSN >= record.LSN, the change is already on disk; skip redo.
- At the end of the Redo phase, the database is restored to the exact physical state it was in at the instant of the crash.
Phase 3: The Undo Phase & Compensation Log Records (CLRs)
- Scans backward from the end of the log, rolling back the changes of all loser transactions.
- For every undone operation, it writes a special Compensation Log Record (CLR) to the log before modifying the page.
- Why CLRs are Crucial: A CLR contains an
UndoNextLSNfield pointing to the next older log record that needs to be undone for that transaction. If the database crashes again during the recovery process, the recovery engine reads the CLR and skips already undone operations, guaranteeing idempotent recovery without infinite loops.
Hands-On Python Implementation: An ARIES Recovery Engine
Let's build a complete, runnable simulation of the ARIES recovery algorithm in Python, demonstrating log record generation, buffer pool dirty page tracking, fuzzy checkpointing, and 3-phase crash recovery:
from dataclasses import dataclass
from typing import Dict, List, Optional, Set

@dataclass
class LogRecord:
    lsn: int
    prev_lsn: Optional[int]
    trans_id: Optional[str]
    record_type: str  # 'UPDATE', 'COMMIT', 'ABORT', 'CLR', 'CHK_BEGIN', 'CHK_END'
    page_id: Optional[int] = None
    redo_val: Optional[str] = None
    undo_val: Optional[str] = None
    undo_next_lsn: Optional[int] = None  # Used exclusively by CLR records

class DatabasePage:
    def __init__(self, page_id: int):
        self.page_id = page_id
        self.value = "INITIAL"
        self.page_lsn = 0

class ARIESEngine:
    def __init__(self):
        self.current_lsn = 0
        self.log: List[LogRecord] = []
        self.disk_pages: Dict[int, DatabasePage] = {i: DatabasePage(i) for i in range(1, 5)}
        self.buffer_pages: Dict[int, DatabasePage] = {}

        # Runtime State
        self.transaction_table: Dict[str, int] = {}  # trans_id -> last_lsn
        self.dirty_page_table: Dict[int, int] = {}    # page_id -> rec_lsn

    def append_log(self, trans_id: Optional[str], r_type: str, page_id: Optional[int] = None,
                   redo_val: Optional[str] = None, undo_val: Optional[str] = None,
                   undo_next: Optional[int] = None) -> LogRecord:
        self.current_lsn += 1
        prev_lsn = self.transaction_table.get(trans_id) if trans_id else None

        rec = LogRecord(
            lsn=self.current_lsn,
            prev_lsn=prev_lsn,
            trans_id=trans_id,
            record_type=r_type,
            page_id=page_id,
            redo_val=redo_val,
            undo_val=undo_val,
            undo_next_lsn=undo_next
        )
        self.log.append(rec)
        if trans_id:
            self.transaction_table[trans_id] = rec.lsn
        return rec

    def write_update(self, trans_id: str, page_id: int, new_val: str):
        page = self.buffer_pages.get(page_id)
        if not page:
            # Read from disk into buffer pool
            page = DatabasePage(page_id)
            page.value = self.disk_pages[page_id].value
            page.page_lsn = self.disk_pages[page_id].page_lsn
            self.buffer_pages[page_id] = page

        old_val = page.value
        rec = self.append_log(trans_id, 'UPDATE', page_id, redo_val=new_val, undo_val=old_val)

        page.value = new_val
        page.page_lsn = rec.lsn

        if page_id not in self.dirty_page_table:
            self.dirty_page_table[page_id] = rec.lsn

    def commit(self, trans_id: str):
        self.append_log(trans_id, 'COMMIT')
        del self.transaction_table[trans_id]

    def flush_page_to_disk(self, page_id: int):
        """Simulates buffer pool stealing / flushing dirty page to disk."""
        page = self.buffer_pages[page_id]
        self.disk_pages[page_id].value = page.value
        self.disk_pages[page_id].page_lsn = page.page_lsn
        if page_id in self.dirty_page_table:
            del self.dirty_page_table[page_id]

    def recover_from_crash(self):
        """Executes the 3-phase ARIES recovery algorithm."""
        print("\n=== STARTING ARIES CRASH RECOVERY ===")

        # --- Phase 1: Analysis Phase ---
        print("\n[PHASE 1: ANALYSIS]")
        tt: Dict[str, int] = {}
        dpt: Dict[int, int] = {}

        for rec in self.log:
            if rec.trans_id:
                if rec.record_type == 'COMMIT':
                    if rec.trans_id in tt:
                        del tt[rec.trans_id]
                else:
                    tt[rec.trans_id] = rec.lsn

            if rec.page_id:
                if rec.page_id not in dpt and rec.record_type in ('UPDATE', 'CLR'):
                    dpt[rec.page_id] = rec.lsn

        print(f"Loser Transactions to Undo: {list(tt.keys())}")
        print(f"Reconstructed Dirty Page Table: {dpt}")

        # --- Phase 2: Redo Phase (Repeat History) ---
        print("\n[PHASE 2: REDO (Repeating History)]")
        min_rec_lsn = min(dpt.values()) if dpt else len(self.log) + 1

        for rec in self.log:
            if rec.lsn < min_rec_lsn:
                continue
            if rec.record_type in ('UPDATE', 'CLR') and rec.page_id:
                disk_page = self.disk_pages[rec.page_id]
                if disk_page.page_lsn < rec.lsn:
                    print(f"Redoing LSN {rec.lsn}: Page {rec.page_id} -> '{rec.redo_val}'")
                    disk_page.value = rec.redo_val
                    disk_page.page_lsn = rec.lsn
                else:
                    print(f"Skipping Redo LSN {rec.lsn}: Page {rec.page_id} already at LSN {disk_page.page_lsn}")

        # --- Phase 3: Undo Phase ---
        print("\n[PHASE 3: UNDO]")
        to_undo: Dict[str, int] = dict(tt)  # trans_id -> last_lsn

        while to_undo:
            # Pick the largest LSN among active losers
            max_trans = max(to_undo, key=lambda t: to_undo[t])
            curr_lsn = to_undo[max_trans]
            rec = next(r for r in self.log if r.lsn == curr_lsn)

            if rec.record_type == 'UPDATE':
                # Write CLR
                undo_next = rec.prev_lsn
                clr = self.append_log(
                    trans_id=rec.trans_id,
                    r_type='CLR',
                    page_id=rec.page_id,
                    redo_val=rec.undo_val,
                    undo_next=undo_next
                )
                print(f"Undoing LSN {rec.lsn} on Page {rec.page_id}: Restoring '{rec.undo_val}' (Logged CLR LSN {clr.lsn})")
                self.disk_pages[rec.page_id].value = rec.undo_val
                self.disk_pages[rec.page_id].page_lsn = clr.lsn

                if undo_next is not None and undo_next > 0:
                    to_undo[max_trans] = undo_next
                else:
                    del to_undo[max_trans]
            elif rec.record_type == 'CLR':
                if rec.undo_next_lsn:
                    to_undo[max_trans] = rec.undo_next_lsn
                else:
                    del to_undo[max_trans]

        print("\n=== RECOVERY COMPLETE: DATABASE CONSISTENT ===")

# --- Simulation Demo ---
if __name__ == "__main__":
    engine = ARIESEngine()

    # 1. Transaction T1 modifies Page 1 and COMMITS
    engine.write_update("T1", 1, "T1_DATA_V1")
    engine.commit("T1")

    # 2. Transaction T2 modifies Page 2 and Page 3 (Does NOT commit)
    engine.write_update("T2", 2, "T2_DATA_V1")
    engine.write_update("T2", 3, "T2_DATA_V1")

    # 3. Buffer pool flushes Page 2 to disk (STEAL policy), but NOT Page 3
    engine.flush_page_to_disk(2)

    # 4. Transaction T3 modifies Page 1 and COMMITS
    engine.write_update("T3", 1, "T3_DATA_V2")
    engine.commit("T3")

    # 5. SIMULATE CRASH! (Buffer pool in RAM vanishes; disk retains flushed state)
    print("--- STATE ON DISK BEFORE RECOVERY ---")
    for pid, p in engine.disk_pages.items():
        print(f"Page {pid}: Value='{p.value}', PageLSN={p.page_lsn}")

    # 6. Execute ARIES Recovery
    engine.recover_from_crash()

    print("\n--- FINAL STATE ON DISK AFTER ARIES RECOVERY ---")
    for pid, p in engine.disk_pages.items():
        print(f"Page {pid}: Value='{p.value}', PageLSN={p.page_lsn}")
Execution Output
--- STATE ON DISK BEFORE RECOVERY ---
Page 1: Value='INITIAL', PageLSN=0
Page 2: Value='T2_DATA_V1', PageLSN=3
Page 3: Value='INITIAL', PageLSN=0
Page 4: Value='INITIAL', PageLSN=0

=== STARTING ARIES CRASH RECOVERY ===

[PHASE 1: ANALYSIS]
Loser Transactions to Undo: ['T2']
Reconstructed Dirty Page Table: {1: 1, 2: 3, 3: 4}

[PHASE 2: REDO (Repeating History)]
Redoing LSN 1: Page 1 -> 'T1_DATA_V1'
Skipping Redo LSN 3: Page 2 already at LSN 3
Redoing LSN 4: Page 3 -> 'T2_DATA_V1'
Redoing LSN 6: Page 1 -> 'T3_DATA_V2'

[PHASE 3: UNDO]
Undoing LSN 4 on Page 3: Restoring 'INITIAL' (Logged CLR LSN 8)
Undoing LSN 3 on Page 2: Restoring 'INITIAL' (Logged CLR LSN 9)

=== RECOVERY COMPLETE: DATABASE CONSISTENT ===

--- FINAL STATE ON DISK AFTER ARIES RECOVERY ---
Page 1: Value='T3_DATA_V2', PageLSN=6
Page 2: Value='INITIAL', PageLSN=9
Page 3: Value='INITIAL', PageLSN=8
Page 4: Value='INITIAL', PageLSN=0
Notice how Page 1 correctly ended up with committed T3_DATA_V2, while Page 2 (which was stolen and written to disk before T2 crashed) was safely undone back to INITIAL via Compensation Log Records!
Real-World Engine Implementations
| Database Engine | Logging Subsystem | Torn Page Protection | Recovery Implementation |
|---|---|---|---|
| PostgreSQL | Append-only pg_wal files (16MB segments) |
Full Page Writes (FPW) on first modification post-checkpoint | Standard Redo from checkpoint REDO pointer + multi-version MVCC visibility |
| MySQL (InnoDB) | Circular ib_logfile Redo Log + Undo Tablespaces |
Doublewrite Buffer (Sequential disk staging before tablespace write) | Strict ARIES: Redo log replay followed by rollback of active transactions in Undo tablespace |
| SQLite | -wal index and frame headers (or Rollback Journal) |
WAL frame checksums & atomic header updates | Passive/restart checkpointing replaying frames to main DB file |
Summary & Architectural Insights
- Durability Without Latency: The STEAL + NO-FORCE policy decouples transactional durability from expensive random page writes by persisting small, sequential WAL logs.
- The Invariant Must Hold:
PageLSN <= FlushedLSNensures that no modified dirty page ever reaches disk before its corresponding WAL log record. - Repeating History Guarantees Correctness: Replaying all operations in Phase 2 simplifies recovery by bringing the database to the exact state at the time of the crash before rolling back loser transactions.
- CLRs Prevent Cascading Failures: Compensation Log Records guarantee that recovery itself is fully idempotent, allowing systems to safely resume recovery even if power fails mid-process.