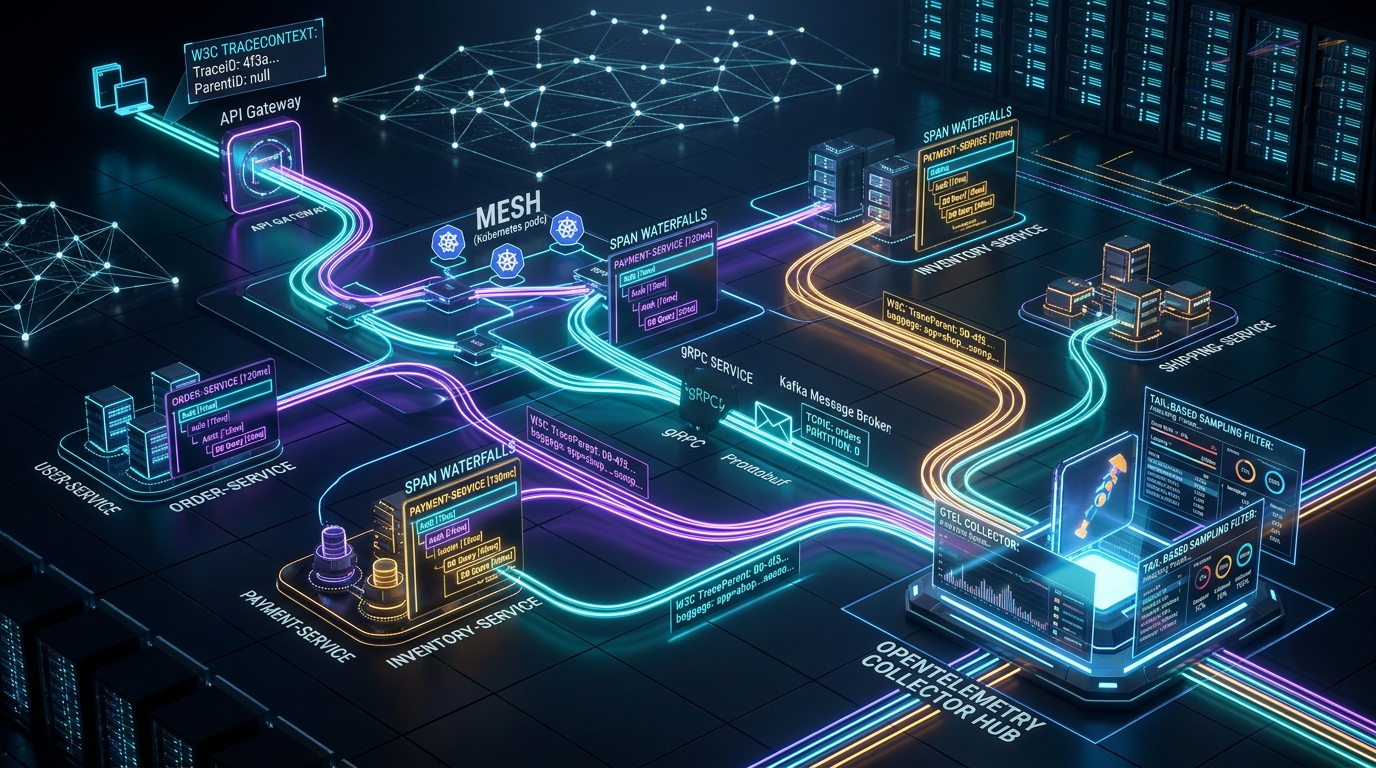
In modern distributed architectures, a single end-user interaction frequently traverses dozens of heterogeneous microservices, serverless functions, asynchronous message queues (Kafka/RabbitMQ), and distributed databases. When an API call fails with a 500 Internal Server Error or encounters a debilitating 3-second p99 latency spike, traditional siloed logs and server-level metrics are completely insufficient.
A single log line saying "Database query timed out" tells you what broke, but gives zero context on why it happened: Which upstream client initiated the request? What authentication tenant triggered it? Which intermediate caching layer had a cache miss? And how much cumulative time was spent across each network hop?
Distributed Tracing solves this visibility breakdown by recording the complete lifecycle of a request as it hops across distributed process boundaries. And today, OpenTelemetry (OTel) has emerged as the universal, vendor-neutral Cloud Native Computing Foundation (CNCF) standard for collecting, processing, and exporting distributed telemetry.
In this comprehensive guide, we dissect the internal architecture of OpenTelemetry tracing, master the W3C TraceContext specification, learn how to propagate context across HTTP, gRPC, and asynchronous worker queues, and configure Tail-Based Sampling to capture 100% of errors and latency outliers without drowning your storage budget.
The Anatomical Anatomy of a Distributed Trace
To master distributed tracing, you must understand its three fundamental building blocks:
Trace Waterfall & Span Hierarchy:

[ Trace: ID = 4bf92f3577b34da6a3ce929d0e0e4736 (Total: 250ms) ]
│
├── [ Span A: Root /checkout HTTP POST ] (Client API Gateway) ────────── 250ms
│   │
│   ├── [ Span B: Auth Middleware verifyToken ] ──────────────── 15ms
│   │
│   ├── [ Span C: gRPC OrderService.CreateOrder ] ────────────── 180ms
│   │   │
│   │   ├── [ Span D: PostgreSQL INSERT INTO orders ] ──────── 45ms
│   │   │
│   │   └── [ Span E: Kafka Producer publish(order.created) ] ─ 25ms
│   │
│   └── [ Span F: Redis Cache Invalidation ] ──────────────────── 10ms
│
└── [ Span G: Async Consumer EmailWorker ] (Linked via TraceContext) ── 80ms- Span: The basic unit of work. Represents a single operation with a start time, end time, name, status code, and rich metadata (attributes and events).
- Trace: A Directed Acyclic Graph (DAG) of spans that represents the end-to-end journey of a single request across the distributed system. All spans within a request share the exact same Trace ID.
- Trace Context: The immutable set of cryptographic IDs and flags that must be passed along the execution path across thread boundaries and network wires.
The W3C TraceContext Standard: Anatomy of traceparent
Historically, tracing systems used incompatible custom HTTP headers (Zipkin's X-B3-TraceId, Datadog's x-datadog-trace-id, AWS X-Ray's X-Amzn-Trace-Id). If an intermediate reverse proxy or third-party service did not recognize your vendor's header, the trace context was silently dropped, resulting in broken, orphaned traces.
The W3C TraceContext standard unifies distributed context under a single standardized HTTP header: traceparent.
W3C traceparent Header Format (4 Hyphen-Separated Hex Fields):

     version -        trace_id        -    parent_id    - trace_flags
       [00]  - [4bf92f3577b34da6...] - [00f067aa0ba9...] -    [01]
        │                │                     │                │
        │                │                     │                └─ 8-bit bitmask (01 = Sampled, 00 = Not Sampled)
        │                │                     └─ 16-hex char (8-byte) Parent Span ID
        │                └─ 32-hex char (16-byte) Global Unique Trace ID
└─ 2-hex char Version (currently 00)| Field | Size | Format & Purpose |
|---|---|---|
| version | 2 hex chars (1 byte) | Specifies the W3C spec version. Currently fixed at 00. |
| trace_id | 32 hex chars (16 bytes) | Globally unique random identifier for the overall distributed trace. Must NOT be all zeros. |
| parent_id | 16 hex chars (8 bytes) | Identifies the specific parent span that issued this outbound request. |
| trace_flags | 2 hex chars (1 byte) | Bitfield controlling downstream behavior. Bit 0 (01) indicates the trace was recorded/sampled by the caller. |
TraceContext vs. Baggage: What Belongs Where?
OpenTelemetry separates distributed context into two distinct concepts:
- TraceContext (
traceparent,tracestate): Contains routing IDs, sampling decisions, and vendor-specific state. Handled strictly by telemetry tracing collectors. - Baggage (
baggageheader): User-defined key-value pairs (e.g.,tenant.id=enterprise_42, user.tier=platinum) that propagate across service boundaries so downstream services and loggers can access contextual business data without re-querying the database.
Context Propagation Across Boundaries: HTTP, gRPC, and Asynchronous Queues
Context propagation is the mechanism that injects trace metadata into carrier payloads before sending, and extracts it on the receiving end to restore the parent-child span relationship.
1. HTTP Propagation in Node.js / TypeScript
import { trace, context, propagation, SpanStatusCode } from '@opentelemetry/api';
import axios from 'axios';

const tracer = trace.getTracer('order-service', '1.0.0');

export async function forwardOrderToPayment(orderId: string, amount: number) {
  // 1. Start a new child span within the current active execution context
  return tracer.startActiveSpan('payment.process_charge', async (span) => {
    try {
      span.setAttribute('order.id', orderId);
      span.setAttribute('payment.amount', amount);

      // 2. Prepare carrier headers object
      const carrier: Record = {};

      // 3. Inject current active trace context (traceparent) into HTTP headers
      propagation.inject(context.active(), carrier);

      console.log('Injected Outbound Headers:', carrier);
      // Outputs: { traceparent: '00-4bf92f3577b34da6a3ce929d0e0e4736-00f067aa0ba902b7-01' }

      // 4. Send outbound HTTP request with trace headers
      const response = await axios.post('https://payment-service.internal/charge', {
        orderId,
        amount,
      }, { headers: carrier });

      span.setStatus({ code: SpanStatusCode.OK });
      return response.data;
    } catch (error: any) {
      span.recordException(error);
      span.setStatus({ code: SpanStatusCode.ERROR, message: error.message });
      throw error;
    } finally {
      span.end();
    }
  });
}
2. Asynchronous Queue Propagation (Kafka / RabbitMQ)
When producing messages to an async message queue like Apache Kafka, HTTP headers are not available. Instead, the trace context must be injected into Kafka Record Headers:
import { context, propagation, defaultTextMapSetter, defaultTextMapGetter } from '@opentelemetry/api';
import { Kafka, Producer, EachMessagePayload } from 'kafkajs';

// --- PRODUCER SIDE ---
export async function publishOrderEvent(producer: Producer, topic: string, event: any) {
  const kafkaHeaders: Record = {};

  // Inject active trace context into headers object
  propagation.inject(context.active(), kafkaHeaders);

  // Convert key-values to Kafka header Buffers
  const messageHeaders = Object.fromEntries(
    Object.entries(kafkaHeaders).map(([k, v]) => [k, Buffer.from(v)])
  );

  await producer.send({
    topic,
    messages: [{
      key: event.orderId,
      value: JSON.stringify(event),
      headers: messageHeaders,
    }],
  });
}

// --- CONSUMER SIDE ---
export async function handleKafkaMessage(payload: EachMessagePayload) {
  const rawHeaders: Record = {};

  // Extract raw string headers from Kafka byte buffers
  for (const [k, v] of Object.entries(payload.message.headers || {})) {
    if (v) rawHeaders[k] = v.toString('utf-8');
  }

  // Extract remote parent context
  const extractedContext = propagation.extract(context.active(), rawHeaders);

  // Run the consumer span linked to the upstream producer's trace!
  const tracer = trace.getTracer('email-worker');
  await context.with(extractedContext, async () => {
    await tracer.startActiveSpan('kafka.consume_order_created', async (span) => {
      try {
        span.setAttribute('messaging.system', 'kafka');
        span.setAttribute('messaging.destination', payload.topic);

        // Process email notification business logic...
        span.setStatus({ code: SpanStatusCode.OK });
      } finally {
        span.end();
      }
    });
  });
}
Sampling Strategies: Head-Based vs. Tail-Based Sampling
In high-throughput environments (e.g. 50,000 requests per second), capturing 100% of traces will quickly generate terabytes of telemetry data, leading to staggering storage bills and high network I/O.
| Sampling Architecture | Where Decision Occurs | Pros & Cons |
|---|---|---|
| Head-Based Sampling | At the root ingress gateway (when request starts) |
+ Low Collector overhead - Completely blind to failures: If you sample at 1%, you miss 99% of crashes, 500 errors, and slow database deadlocks. |
| Tail-Based Sampling | At the OpenTelemetry Collector (after trace completes) |
+ 100% Error & Latency Capture: Retains all spans from failed requests or traces taking > 1,000ms, while aggressively sampling boring 200 OK spans down to 0.1%. - Requires collector memory buffering. |
Production OpenTelemetry Collector Pipeline with Tail Sampling
The OpenTelemetry Collector is a high-performance proxy written in Go that receives, processes, filters, and exports telemetry data. Below is a production-ready otel-collector-config.yaml featuring tail-based sampling filters:
receivers:
  otlp:
    protocols:
      grpc:
        endpoint: 0.0.0.0:4317
      http:
        endpoint: 0.0.0.0:4318

processors:
  # 1. Batch spans to optimize network throughput to backend
  batch:
    send_batch_size: 1024
    timeout: 1s

  # 2. Tail-Based Sampling Processor
  tail_sampling:
    decision_wait: 5s # Buffer spans in memory for 5 seconds to assemble full trace
    num_traces: 50000
    expected_new_traces_per_sec: 2000
    policies:
      # Rule 1: Always keep 100% of traces with an ERROR status
      - name: drop-errors-never
        type: status_code
        status_code: { status_codes: [ ERROR ] }

      # Rule 2: Always keep 100% of traces with duration > 1500ms (p99 latency)
      - name: slow-traces-policy
        type: latency
        latency: { threshold_ms: 1500 }

      # Rule 3: Always keep traces for critical VIP tenants
      - name: vip-tenants
        type: string_attribute
        string_attribute:
          key: tenant.tier
          values: [ "enterprise", "vip" ]

      # Rule 4: Sample remaining fast/successful traces at 2%
      - name: probabilistic-sample-ok
        type: probabilistic
        probabilistic: { sampling_percentage: 2.0 }

  # 3. Memory Limiter to protect collector process from OOM
  memory_limiter:
    check_interval: 1s
    limit_percentage: 75
    spike_limit_percentage: 20

exporters:
  # Export sampled traces to Jaeger / Tempo
  otlp/jaeger:
    endpoint: jaeger:4317
    tls:
      insecure: true

  # Export metrics to Prometheus
  prometheus:
    endpoint: 0.0.0.0:8889

service:
  pipelines:
    traces:
      receivers: [ otlp ]
      processors: [ memory_limiter, tail_sampling, batch ]
      exporters: [ otlp/jaeger ]
Summary & Engineering Best Practices
To ensure robust, high-fidelity distributed observability across enterprise microservices:
- Enforce W3C TraceContext Uniformity: Reject proprietary tracing headers and standardize all internal reverse proxies, API gateways, and microservices on standard
traceparentandtracestate. - Propagate Context Across Async Hops: Never let message queues (Kafka, SQS, RabbitMQ) become dead ends for tracing. Always inject trace context into message metadata headers.
- Implement Tail-Based Sampling: Stop relying solely on naive head-based sampling that misses rare production bugs. Use the OpenTelemetry Collector's
tail_samplingprocessor to guarantee 100% retention on HTTP 5xx responses and latency spikes. - Sanitize Baggage: Leverage OpenTelemetry Baggage for contextual identifiers (e.g. tenant IDs, region codes), but strictly prohibit secrets, tokens, and PII from crossing network boundaries in plaintext.