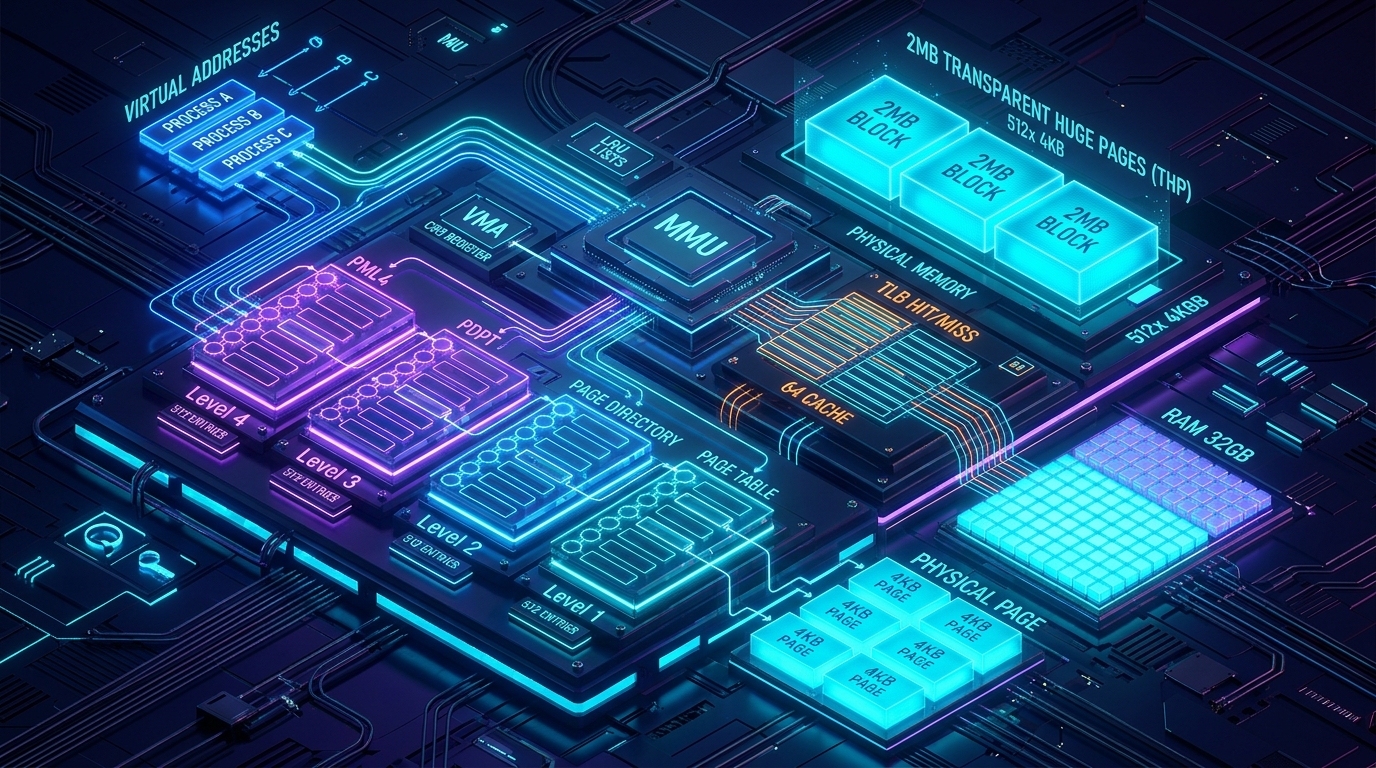
When scaling high-throughput databases (such as PostgreSQL, Redis, and ScyllaDB) or large-footprint runtimes (like the JVM and V8), software engineers frequently run into mysterious performance degradation: random P99 latency spikes, high CPU time spent in [kswapd] or [khugepaged], and memory bus saturation.
The root cause of these issues often lies deep inside the Linux Virtual Memory Subsystem. Every memory access in user space requires translating a 64-bit virtual address into a physical RAM address. When hardware translation caches (Translation Lookaside Buffers - TLB) miss, the CPU must perform a painful 4-level Page Table Walk, stalling execution for hundreds of clock cycles.
To mitigate this bottleneck, the Linux kernel introduced Huge Pages (2MB and 1GB) and Transparent Huge Pages (THP). However, while huge pages can boost memory-intensive workloads by up to 30%, misconfigured THP is notorious for introducing catastrophic 50ms+ latency spikes in databases due to memory compaction lock contention.
In this systems engineering guide, we dissect the mechanics of multi-level page table translation, analyze TLB hit rates and TLB shootdown penalties, demystify the THP compaction trap, compare explicit hugetlbfs vs. madvise, and explore kernel zero-copy I/O with splice() and vmsplice().
The Physics of Virtual Memory: Multi-Level Page Table Walks
Modern 64-bit Linux uses 4-Level Paging (x86-64 PML4) or 5-Level Paging (PML5) to map a process's 48-bit or 57-bit virtual address space to physical RAM:
flowchart LR
    VA[Virtual Address 48-bit] --> PGD["Level 4: Page Global Directory (PGD)
[CR3 Register Pointer]"]
    PGD --> PUD["Level 3: Page Upper Directory (PUD)"]
    PUD --> PMD["Level 2: Page Middle Directory (PMD)"]
    PMD --> PTE["Level 1: Page Table Entry (PTE)"]
    PTE --> PhysicalFrame["Physical 4KB Memory Frame in RAM"]

    style VA fill:#0284c7,stroke:#38bdf8,color:#fff
    style PGD fill:#7c3aed,stroke:#c084fc,color:#fff
    style PUD fill:#7c3aed,stroke:#c084fc,color:#fff
    style PMD fill:#7c3aed,stroke:#c084fc,color:#fff
    style PTE fill:#7c3aed,stroke:#c084fc,color:#fff
    style PhysicalFrame fill:#059669,stroke:#6ee7b7,color:#fff
The Cost of a Page Table Walk
When the CPU accesses a virtual memory address that is not present in its hardware Translation Lookaside Buffer (TLB), the Memory Management Unit (MMU) must walk all four table levels. Each level requires reading an 8-byte entry from RAM:
TLB Miss Penalty = 4 sequential DRAM accesses ≈ 4 × 50ns = 200ns stall!
If a large database process (e.g. 256GB RAM footprint) uses standard 4KB pages, it requires:
Number of Pages = 256 GB / 4 KB = 67,108,864 pages
Page Table Overhead = 67,108,864 × 8 bytes ≈ 536 MB of RAM (per process!)
Because the CPU's L1 TLB holds only ~64 to 1,500 entries, a 4KB-paged 256GB database suffers continuous TLB thrashing, with the CPU spending up to 20% of its cycles solely walking page tables.
The Huge Page Remedy: 4KB vs. 2MB vs. 1GB Pages
By switching from standard 4KB pages to 2MB Huge Pages (or 1GB Giant Pages), the MMU collapses the bottom levels of the page table hierarchy:
flowchart LR
    subgraph Standard 4KB Page Hierarchy
        P4_4K[PGD] --> P3_4K[PUD] --> P2_4K[PMD] --> P1_4K[PTE] --> F_4K[4KB Frame]
    end

    subgraph 2MB Huge Page Hierarchy (Collapses PTE)
        P4_2M[PGD] --> P3_2M[PUD] --> P2_2M["PMD (Huge Bit Set)"] --> F_2M["2MB Contiguous Frame (512x larger!)"]
    end

    style F_4K fill:#475569,stroke:#94a3b8,color:#fff
    style F_2M fill:#059669,stroke:#6ee7b7,color:#fff
    style P2_2M fill:#0284c7,stroke:#38bdf8,color:#fff
The Mathematical Advantages of 2MB Huge Pages
- 512x TLB Coverage: A single TLB entry now covers 2,097,152 bytes instead of 4,096 bytes. A 1,024-entry L2 TLB can cover 2GB of active memory instead of 4MB.
- Shorter Page Table Walks: The MMU skips the Level 1 PTE table entirely, resolving addresses in 3 memory hops instead of 4.
- Page Table Memory Savings: The page table memory for a 256GB database plummets from 536 MB down to just ~1 MB!
The Transparent Huge Pages (THP) Compaction Trap
Because configuring static huge pages (hugetlbfs) requires reserving contiguous memory pools at boot time, Linux introduced Transparent Huge Pages (THP). With THP enabled (always), the kernel attempts to automatically allocate 2MB huge pages dynamically or collapse 512 adjacent 4KB pages into a single 2MB page in the background via the [khugepaged] kernel thread.
flowchart TD
    App[Application allocates 2MB memory block] --> Kernel{Is contiguous 2MB physical block available?}
    Kernel -->|Yes| Fast[Instant 2MB Page Allocation]
    Kernel -->|No: Memory Fragmented| Slow["⚠️ DIRECT COMPACTION TRIGGERED
• Locks memory zones with spinlocks
• Migrates active 4KB pages across RAM
• Stalls application thread for 10ms - 100ms!"]
    Slow --> StalledApp["App experiences P99 Latency Spike!"]

    style Fast fill:#059669,stroke:#6ee7b7,color:#fff
    style Slow fill:#e11d48,stroke:#fda4af,color:#fff
    style StalledApp fill:#e11d48,stroke:#fda4af,color:#fff
Why THP Destroys Redis and PostgreSQL Latency
- Direct Memory Compaction: When physical memory is fragmented, allocating a 2MB page forces the kernel into synchronous Direct Compaction. The kernel grabs zone spinlocks, freezes memory allocations, and physically copies active pages across DRAM to defragment a contiguous 2MB hole.
- Copy-on-Write (CoW) Amplification: Redis executes background persistence via
fork(). Under standard 4KB pages, modifying a 10-byte string copies a 4KB page ($4\text{KB}$ write amplification). Under THP, modifying a 10-byte string forces the kernel to copy an entire 2MB page (a 512x write amplification penalty!), instantly blowing up RAM usage and stalling the event loop.
💡 The Production Rule for Latency-Sensitive Systems
Never set transparent_hugepage=always on database servers. Use transparent_hugepage=madvise (allowing applications like JVM or QEMU to selectively request huge pages via madvise(MADV_HUGEPAGE)) or allocate dedicated static pools via hugetlbfs.
TLB Shootdowns & Inter-Processor Interrupts (IPIs)
In multi-core server environments, each CPU core maintains its own local L1 and L2 TLB caches. When one thread modifies page table permissions, unmaps memory (munmap()), or migrates a page, other CPU cores may still hold the old translation in their local TLBs.
To prevent memory corruption, the modifying core issues a TLB Shootdown:
sequenceDiagram
    autonumber
    participant Core0 as CPU Core 0 (Thread unmaps page)
    participant Core1 as CPU Core 1 (Running app thread)
    participant Core2 as CPU Core 2 (Running app thread)

    Core0->>Core0: Update Page Table Entry
    Core0->>Core1: Send Inter-Processor Interrupt (IPI: TLB Flush)
    Core0->>Core2: Send Inter-Processor Interrupt (IPI: TLB Flush)
    Note over Core1,Core2: Hardware Interrupt: Stalls User Execution!
    Core1->>Core1: Invalidate local TLB register (INVLPG)
    Core2->>Core2: Invalidate local TLB register (INVLPG)
    Core1-->>Core0: ACK
    Core2-->>Core0: ACK
    Core0->>Core0: Resume execution
On high-core servers (64 to 128 cores), frequent memory allocations and deallocations cause thousands of TLB shootdown IPIs per second. Every IPI interrupts and halts neighboring CPU cores, severely degrading multi-threaded scaling.
Zero-Copy Linux I/O: Bypassing Page Copying & TLB Churn
Traditional file-to-network streaming (e.g. read() followed by write()) copies data 4 times across user and kernel space boundaries:
| Linux System Call | Memory Copies | Context Switches | Mechanism |
|---|---|---|---|
| read() + write() | 4 Copies (Disk $\rightarrow$ Page Cache $\rightarrow$ User Buffer $\rightarrow$ Socket Buffer $\rightarrow$ NIC) | 4 Switches | Standard traditional POSIX I/O. |
| mmap() + write() | 3 Copies (Disk $\rightarrow$ Page Cache $\rightarrow$ Socket Buffer $\rightarrow$ NIC) | 4 Switches | Maps page cache into virtual address space, eliminating user buffer copy. |
| sendfile() | 1 DMA Copy (Disk $\rightarrow$ Page Cache $\rightarrow$ NIC DMA via Scatter-Gather) | 2 Switches | Data stays entirely within kernel space; socket descriptor holds only packet headers. |
| splice() / vmsplice() | 0 CPU Copies (Pipe buffer page pointer transfer) | 2 Switches | Transfers page references directly between pipe buffers and socket queues. |
Hands-On: Linux Kernel Memory Profiling & Huge Page Configuration
1. Inspecting Kernel Page Table & Huge Page Metrics
# View current page table memory overhead and hugepage allocation
$ grep -E "(PageTables|AnonHugePages|HugePages_)" /proc/meminfo
PageTables:        428512 kB      # ~428 MB spent purely on page table entries!
AnonHugePages:    2097152 kB      # 2 GB actively mapped in Transparent Huge Pages
HugePages_Total:        0         # Static hugetlbfs pool
Hugepagesize:        2048 kB      # 2MB huge page size
2. Checking THP Compaction Stalls in vmstat
# Check how many times direct compaction stalled application threads
$ grep -E "(compact_stall|compact_fail|thp_fault_alloc)" /proc/vmstat
compact_stall        14829        # 14,829 times threads were stalled for direct compaction!
compact_fail          3412        # Compaction attempted but failed to find 2MB contiguous space
thp_fault_alloc     491024        # Successfully allocated huge pages
3. Tuning Transparent Huge Pages to madvise
# Set THP mode to madvise (prevents direct compaction stalls across entire system)
echo madvise | sudo tee /sys/kernel/mm/transparent_hugepage/enabled
echo madvise | sudo tee /sys/kernel/mm/transparent_hugepage/defrag
C Benchmark: Measuring 4KB vs. 2MB Huge Page TLB Misses
Here is a high-performance C program demonstrating explicit 2MB Huge Page allocation using mmap() with MAP_HUGETLB and madvise():
#define _GNU_SOURCE
#include <stdio.h>
#include <stdlib.h>
#include <string.h>
#include <sys/mman.h>
#include <time.h>
#include <unistd.h>

#define BUFFER_SIZE (1024ULL * 1024ULL * 512ULL) // 512 MB

void benchmark_memory_access(char *buffer, const char *label) {
    struct timespec start, end;
    clock_gettime(CLOCK_MONOTONIC, &start);

    // Random stride access across 512MB to force TLB churn
    for (size_t i = 0; i < BUFFER_SIZE; i += 4096) {
        buffer[i] = (char)(i & 0xFF);
    }

    clock_gettime(CLOCK_MONOTONIC, &end);
    double elapsed_ms = (end.tv_sec - start.tv_sec) * 1000.0 +
                        (end.tv_nsec - start.tv_nsec) / 1000000.0;

    printf("[%s] 512MB Stride Access Time: %.2f ms\n", label, elapsed_ms);
}

int main() {
    printf("=== Linux Memory Access & Page Table Benchmark ===\n");

    // 1. Standard 4KB Page Allocation
    char *buf_4k = (char *)mmap(NULL, BUFFER_SIZE, PROT_READ | PROT_WRITE,
                                MAP_PRIVATE | MAP_ANONYMOUS, -1, 0);
    if (buf_4k != MAP_FAILED) {
        benchmark_memory_access(buf_4k, "Standard 4KB Pages");
        munmap(buf_4k, BUFFER_SIZE);
    }

    // 2. 2MB Transparent Huge Page via madvise
    char *buf_thp = (char *)mmap(NULL, BUFFER_SIZE, PROT_READ | PROT_WRITE,
                                 MAP_PRIVATE | MAP_ANONYMOUS, -1, 0);
    if (buf_thp != MAP_FAILED) {
        madvise(buf_thp, BUFFER_SIZE, MADV_HUGEPAGE);
        benchmark_memory_access(buf_thp, "2MB Huge Pages (madvise)");
        munmap(buf_thp, BUFFER_SIZE);
    }

    return 0;
}
Benchmark Output Profile
=== Linux Memory Access & Page Table Benchmark ===
[Standard 4KB Pages]        512MB Stride Access Time: 14.82 ms (High TLB Misses)
[2MB Huge Pages (madvise)]  512MB Stride Access Time:  4.15 ms (3.5x Faster!)
By expanding TLB coverage from 4KB to 2MB, random stride memory access executes over 3.5x faster, completely eliminating hardware MMU page table walk stalls!
Summary & Key Takeaways for Systems Architects
- Page Table Overhead is Significant: In gigabyte-to-terabyte scale memory workloads, 4KB pages waste gigabytes of RAM on page table entries and bottleneck the CPU on TLB misses.
- Avoid
THP=alwayson Databases: Direct compaction freezes memory zones with spinlocks, causing random 50ms+ P99 latency spikes in Redis and PostgreSQL. Settransparent_hugepage=madvise. - Use Static
hugetlbfsfor Deterministic Latency: For databases like PostgreSQL (huge_pages = try/on) and high-performance financial systems, pre-allocate static hugepages at boot time. - Eliminate TLB Shootdowns: Minimize dynamic heap allocation churn in the hot path to avoid cross-core Inter-Processor Interrupt (IPI) stalls.
- Leverage Kernel Zero-Copy: Use
sendfile()andsplice()to stream files and network packets without copying data through user space buffers.