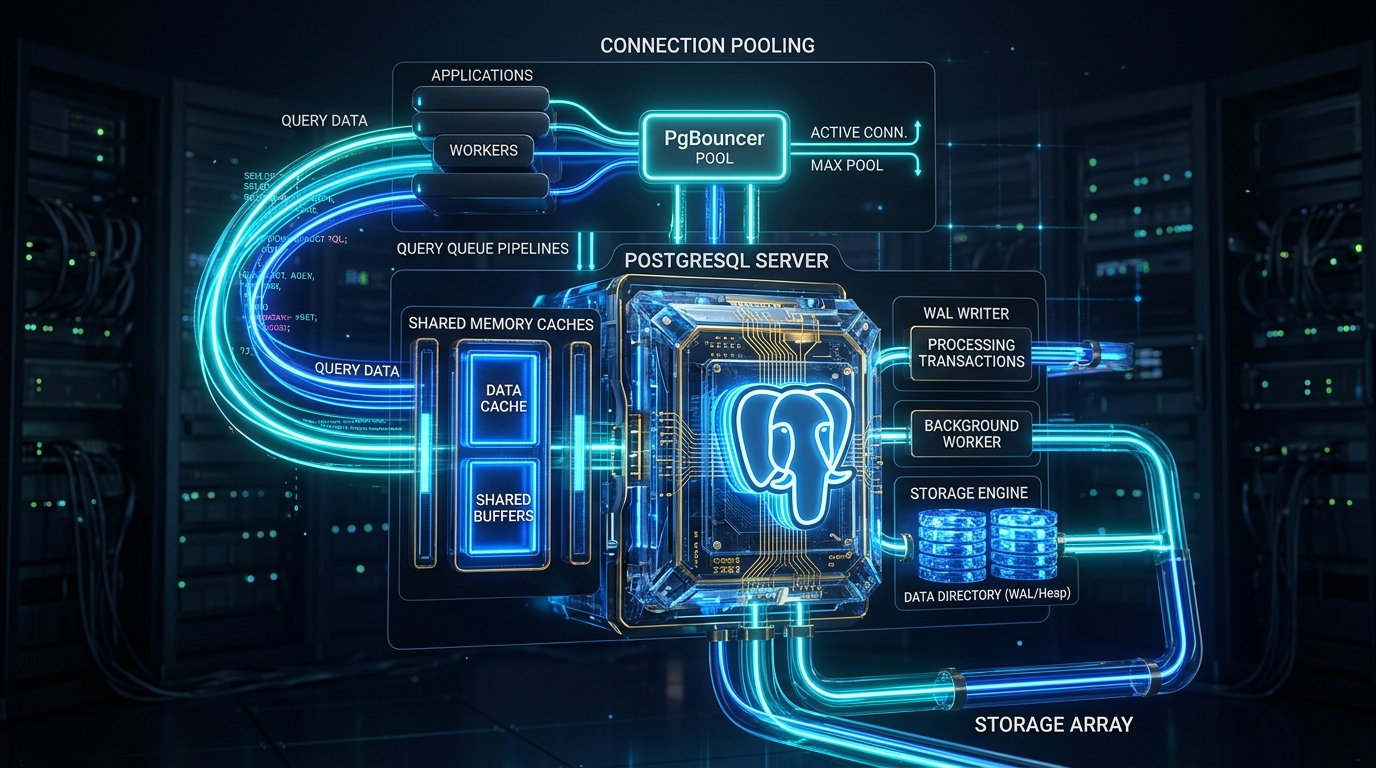
PostgreSQL is one of the most reliable and feature-rich relational databases available. However, as web applications scale into thousands of concurrent requests, default configurations quickly encounter severe performance ceilings: process-per-connection RAM bloat, CPU context-switching overhead, query queue latency, and table bloat from unmanaged MVCC dead tuples. In this deep architectural guide, we explore how to scale PostgreSQL for high-throughput production workloads using connection pooling (PgBouncer), memory parameter tuning, modern indexing strategies (BRIN, B-Tree, GIN, Partial), and proactive autovacuum maintenance.
1. The Connection Concurrency Dilemma: Why max_connections = 1000 Kills Performance
Unlike database engines that employ lightweight threading models, PostgreSQL uses a process-based connection model. Every active client connection spawns a dedicated backend OS process that requires its own private memory allocations (work_mem, stack space, socket buffers).
When high-concurrency traffic floods PostgreSQL with hundreds of direct client connections, two fatal bottlenecks occur:
- CPU Context-Switching Thrashing: The Linux kernel spends more CPU cycles scheduling and context-switching between hundreds of waiting processes than actually executing query instructions.
- L1/L2/L3 CPU Cache Eviction: Constant process switching flushes CPU memory caches, leading to dramatic latency spikes across all database queries.
The Ideal PostgreSQL Connection Formula
Mathematical benchmarks and testing at major cloud providers show that optimal PostgreSQL throughput is achieved when direct backend connections remain close to:
Optimal Connections = (Core Count * 2) + Effective Spindle / Disk CountOn an 8-core CPU server with NVMe SSDs, setting PostgreSQL's internal max_connections = 60 - 100 delivers significantly higher transaction throughput and lower P99 latency than setting it to 1,000.
2. Implementing PgBouncer for High-Density Connection Pooling
To support thousands of frontend web workers (such as PHP-FPM pools, Node.js clusters, or Go routines) without overwhelming the database process table, an external connection pooler like PgBouncer is mandatory.
Transaction Pooling Mode Architecture
PgBouncer offers three pooling modes: Session, Transaction, and Statement. For 99% of web applications and REST APIs, Transaction Pooling is the gold standard: a server backend connection is assigned to a client only for the exact duration of a single database transaction, then immediately returned to the pool.
# /etc/pgbouncer/pgbouncer.ini
[databases]
mydb = host=127.0.0.1 port=5432 dbname=production_db auth_user=postgres

[pgbouncer]
listen_addr = 0.0.0.0
listen_port = 6432
auth_type = scram-sha-256
auth_file = /etc/pgbouncer/userlist.txt

# Transaction pooling mode for maximum concurrency
pool_mode = transaction

# Global and per-database connection limits
max_client_conn = 5000
default_pool_size = 40
min_pool_size = 10
reserve_pool_size = 5
reserve_pool_timeout = 5
max_db_connections = 80
Transaction Mode Caveat:
In transaction pooling mode, session-level constructs like LISTEN/NOTIFY, temporary tables, and session-level prepared statements cannot be shared across different transactions. Ensure your ORM (e.g. Laravel PDO, Hibernate, or Prisma) uses connection-level prepared statement emulation or named statement resets.
3. Tuning Critical PostgreSQL Memory Parameters
PostgreSQL ships with conservative default memory settings designed to boot on minimal hardware. For a dedicated database server, tune the following key parameters in postgresql.conf:
A. shared_buffers
Determines how much dedicated memory PostgreSQL uses for caching table and index pages. Set this to 25% of total system RAM (e.g., 8 GB on a 32 GB RAM server). Allocating more than 40% usually yields diminishing returns because PostgreSQL relies heavily on the Linux OS Page Cache for double buffering.
B. effective_cache_size
An advisory parameter that gives the PostgreSQL query planner an estimate of total memory available for disk caching (shared_buffers + Linux Page Cache). Set this to 50% - 75% of total system RAM (e.g., 24 GB on a 32 GB RAM server). A higher value encourages the planner to use index scans instead of full table scans.
C. work_mem
Specifies the amount of RAM used by internal sort operations (ORDER BY, DISTINCT) and hash tables (JOIN, GROUP BY) per query node. Unlike shared_buffers, this is allocated dynamically per operation.
-- Formula: (Total Available RAM - shared_buffers) / (max_connections * 3)
-- For a 32GB server with 80 max_connections:
work_mem = '32MB';
maintenance_work_mem = '1GB';
4. Modern Indexing Strategies for Large Data Sets
1. Partial Indexes (Filtered Lookups)
If you frequently query a subset of rows (such as status = 'active' or deleted_at IS NULL), a partial index reduces index size by up to 90% and keeps the index entirely inside RAM buffers:
-- Instead of indexing all 10M rows:
CREATE INDEX idx_orders_unprocessed
ON orders (created_at)
WHERE status = 'pending';
2. BRIN (Block Range Index) for Time-Series / Append-Only Tables
For large append-only tables (logs, audit events, sensor telemetry) where timestamps are naturally sorted, standard B-Trees consume gigabytes of RAM. A BRIN index stores only the minimum and maximum values per block range, shrinking index size from hundreds of MBs to a few KBs:
-- 100M row event table: BRIN takes < 1MB vs 2.5GB for B-Tree
CREATE INDEX idx_audit_logs_timestamp_brin
ON audit_logs USING BRIN (created_at);
3. Covering Indexes (Index-Only Scans with INCLUDE)
Avoid table heap lookups completely by including supplementary columns in the index payload:
CREATE INDEX idx_users_email_covering
ON users (email)
INCLUDE (id, name, role, last_login_at);
5. Taming Table Bloat with Proactive Autovacuum Tuning
PostgreSQL uses Multi-Version Concurrency Control (MVCC). When a row is updated or deleted, PostgreSQL does not overwrite the physical disk block; it marks the old tuple as dead and writes a new tuple. Autovacuum is responsible for reclaiming dead tuple space and preventing transaction ID wraparound.
Default autovacuum triggers only when 20% of a table is modified. On a 10-million row table, autovacuum won't run until 2 million updates occur, causing massive disk bloat and sluggish sequential scans.
# Aggressive autovacuum tuning for high write throughput
autovacuum = on
autovacuum_max_workers = 4
autovacuum_naptime = 15s

# Trigger vacuum after 50 dead tuples + 2% table changes
autovacuum_vacuum_threshold = 50
autovacuum_vacuum_scale_factor = 0.02

# Trigger analyze after 50 changes + 1% table changes
autovacuum_analyze_threshold = 50
autovacuum_analyze_scale_factor = 0.01

# Increase vacuum I/O cost limit for faster completion on NVMe
autovacuum_vacuum_cost_limit = 2000
autovacuum_vacuum_cost_delay = 2ms
6. Summary & Production Benchmarking Checklist
| Area | Target Configuration | Impact |
|---|---|---|
| Connection Pool | PgBouncer (Transaction Mode, pool: 40-80) | Eliminates CPU context-switching thrash under 5k+ client concurrency |
| Buffer Cache | shared_buffers = 25% RAM, effective_cache_size = 75% RAM |
Maximizes in-memory page hits and optimal query plans |
| Indexing | Partial indexes & BRIN on append-only time-series data | Reduces RAM cache footprint by up to 90% |
| MVCC Cleanup | autovacuum_vacuum_scale_factor = 0.02 |
Prevents table bloat and preserves index-only scans |
Conclusion
High-concurrency PostgreSQL performance is not achieved by simply buying larger cloud instances with more CPU cores. By placing PgBouncer in front of your database, capping internal backend connections, sizing memory caches, implementing specialized index strategies, and aggressively reclaiming dead tuples with autovacuum, your database can effortlessly process tens of thousands of transactions per second with microsecond consistency.