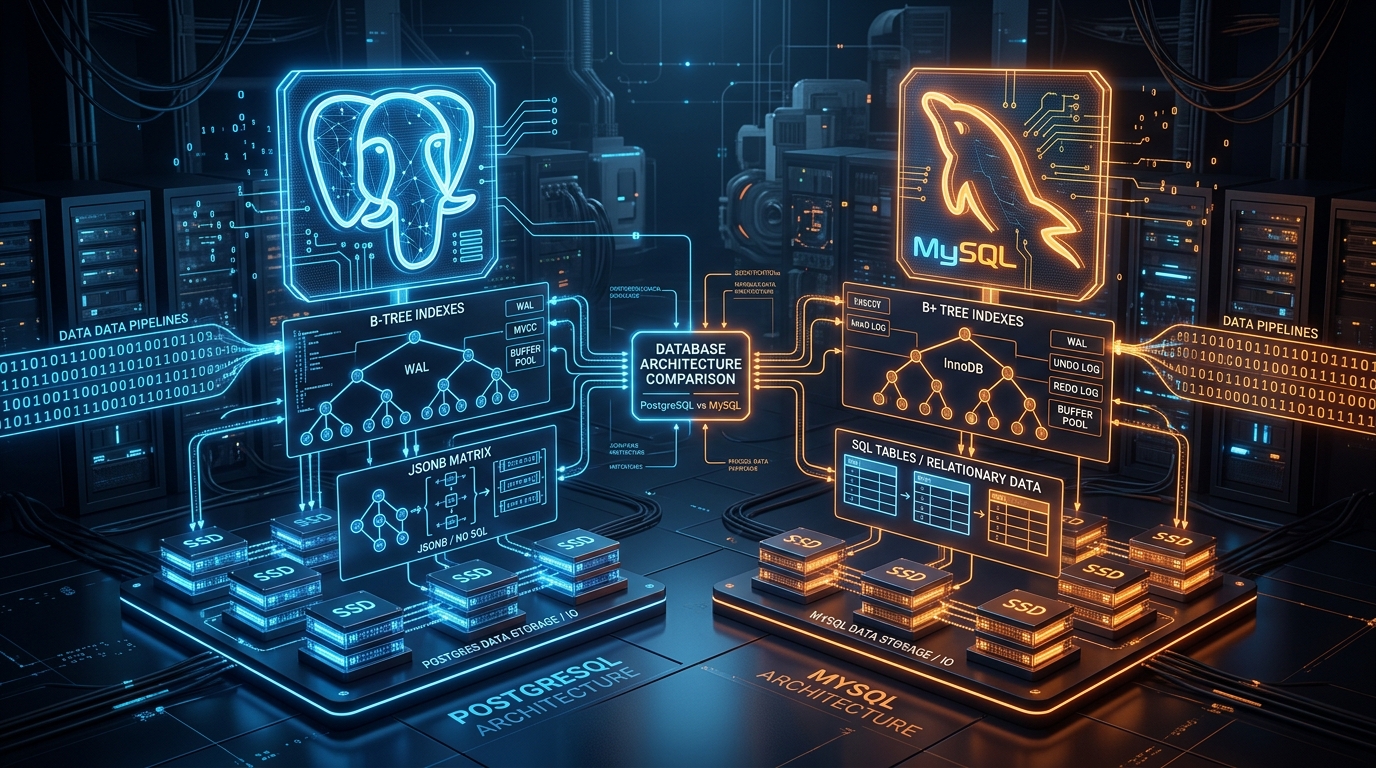
For over two decades, the choice between PostgreSQL and MySQL has been the foundational architectural decision for relational database engineering. While online blog debates often devolve into surface-level feature checklists, production system designers know that the true differences lie in fundamental engine internals: Multi-Version Concurrency Control (MVCC) architectures, write-ahead logging mechanisms, JSON indexing data structures, and connection memory models.
Both engines have matured aggressively. MySQL (under Oracle) has added powerful window functions, CTEs, and multi-valued JSON indexes, while PostgreSQL has consolidated its reputation as the "universal database" with unmatched extensibility (PostGIS, pgvector, BRIN indexing). In this architectural guide, we dissect the internal differences between PostgreSQL and MySQL, examine performance under high write vs. read concurrency, and establish a clear decision framework for modern application stacks.
1. Core Architectural Differences: MVCC & Storage Engines
The most consequential difference between PostgreSQL and MySQL InnoDB is how they implement Multi-Version Concurrency Control (MVCC) to provide ACID transaction isolation:
| Architectural Vector | PostgreSQL (Heap + VACUUM) | MySQL (InnoDB Clustered Index + Undo Logs) |
|---|---|---|
| Row Update Mechanism | Appends a new version (tuple) of the row directly to the table heap (Out-of-place update). | Modifies the row in-place in the clustered index and records the old version in the Undo Tablespace. |
| Dead Tuple Cleanup | Requires VACUUM / autovacuum workers to reclaim space occupied by dead rows. | Purge Threads automatically clean up undo log pages once transactions complete. |
| Primary Key Organization | Heap-organized table. Primary key is a secondary B-Tree pointing to a physical Tuple ID (TID). | Clustered Index. Table rows are physically stored directly in the primary key B+Tree leaf pages. |
| Process Model | Process-per-connection (Requires connection poolers like PgBouncer). | Thread-per-connection (Lower memory overhead per connection). |
2. JSON Document Storage: PostgreSQL JSONB vs. MySQL JSON
Both databases support native JSON data types, but their indexing and query execution paths differ radically:
PostgreSQL: Binary JSONB + GIN Indexing
PostgreSQL parses JSON text at write time and stores it in a decomposed binary format (JSONB). It allows you to create a Generalized Inverted Index (GIN) on the entire JSON document:
-- PostgreSQL: Create a GIN index on the entire metadata JSONB document
CREATE INDEX idx_orders_metadata ON orders USING gin (metadata);

-- Lightning-fast O(log N) containment query using the @> operator:
SELECT * FROM orders WHERE metadata @> '{"tier": "enterprise", "country": "US"}';
MySQL: JSON Type + Functional & Multi-Valued Indexes
MySQL stores JSON in an optimized binary format, but searching inside JSON traditionally required creating generated virtual columns or Multi-Valued Indexes (for arrays):
-- MySQL 8.0+: Multi-valued index for JSON arrays
CREATE INDEX idx_user_tags ON users ( (CAST(tags AS UNSIGNED ARRAY)) );

-- Query using MEMBER OF:
SELECT * FROM users WHERE 42 MEMBER OF(tags);
JSONB is substantially more powerful for dynamic, arbitrary semi-structured schemas because a single GIN index indexes all keys and values automatically. MySQL requires you to anticipate specific query paths using functional indexes.
3. Advanced Indexing Strategies: Beyond Standard B-Trees
PostgreSQL offers the most versatile indexing engine in the relational world, unlocking massive performance optimizations for specialized datasets:
| Index Type | PostgreSQL Support | MySQL Support | Optimal Use Case |
|---|---|---|---|
| B-Tree / B+Tree | ✓ Yes | ✓ Yes | Standard equality and range lookups (=, <, >, BETWEEN). |
| GIN (Inverted) | ✓ Yes | ✗ Limited | Full-text search, arrays, and unstructured JSONB documents. |
| BRIN (Block Range) | ✓ Yes | ✗ No | Multi-billion row append-only timeseries data (Consumes 99% less disk space than B-Tree). |
| Partial / Filtered Indexes | ✓ Yes (WHERE status = 'pending') |
✗ No | Indexing only active subsets of rows; shrinks index size by up to 90%. |
| PostGIS & Vector (pgvector) | ✓ Yes | ✗ Limited | Advanced geospatial calculations (R-Tree) and AI vector embeddings. |
4. Concurrency & Locking: Queue Processing with SKIP LOCKED
When building background queue processors, message dispatchers, or inventory booking systems, multiple worker processes compete for the next available record:
-- Both PostgreSQL and MySQL 8.0+ support non-blocking row locks:
SELECT * FROM job_queue
WHERE status = 'pending'
ORDER BY priority DESC, id ASC
LIMIT 1
FOR UPDATE SKIP LOCKED;
SKIP LOCKED instructs the database engine to skip past rows currently locked by other concurrent transactions—enabling lock-free parallel worker consumption without contention or deadlocks.
5. The Strategic Decision Framework
When to Choose PostgreSQL:
- → Complex analytical queries: Hash joins, parallel query execution, and rich CTEs.
- → Semi-structured / NoSQL workloads: Extensive use of
JSONBwith dynamic nested filtering. - → Geospatial & AI applications: Native PostGIS routing or pgvector similarity search.
- → Append-only timeseries data: Billion-row event logs utilizing BRIN indexes.
When to Choose MySQL (InnoDB):
- → High-volume simple OLTP read/write workloads: Massive e-commerce inventory with predictable primary key access.
- → Zero-maintenance vacuum overhead: Clustered index in-place updates eliminate table bloat concerns without autovacuum tuning.
- → High-connection environments: Thread-per-connection architecture handles hundreds of direct client connections with less RAM.
- → Broad managed hosting support: Universal drop-in availability across every cloud and shared hosting provider.
Conclusion
There is no longer a generic "better" database—both PostgreSQL and MySQL are world-class, ultra-reliable storage engines. Choose PostgreSQL when your domain demands rich extensibility, dynamic JSONB indexing, and complex analytical logic; choose MySQL when you require simple, blazing-fast clustered OLTP throughput with minimal maintenance overhead.