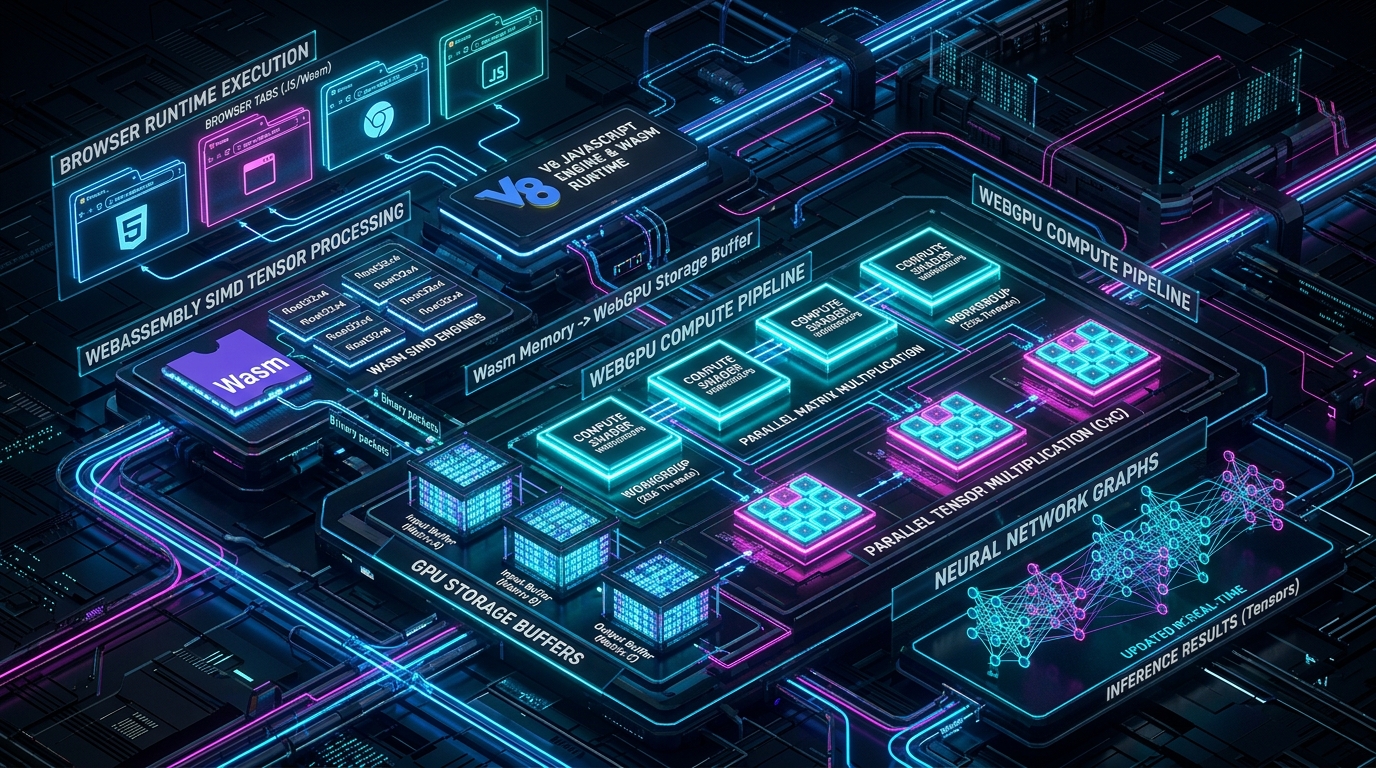
For the past three decades, web browsers operated under a fundamental architectural constraint: computationally heavy tasks—such as 3D physics, cryptographic hashing, image processing, and AI model inference—had to be offloaded to remote cloud servers. The browser was merely a rendering terminal.
Today, that boundary has dissolved. With the convergence of WebAssembly (Wasm) 128-bit SIMD and WebGPU, modern browsers (Chrome, Edge, Firefox, Safari) can harness the raw, bare-metal compute power of client hardware. By granting web applications direct access to GPU compute pipelines, workgroups, and tensor operations, developers can now run quantized Large Language Models (LLMs), Whisper audio transcription, and computer vision models entirely inside a web tab.
Running AI locally in the browser unlocks three transformative advantages: Zero Server Infrastructure Costs ($0 per token), Sub-millisecond Local Latency, and Absolute User Privacy (data never leaves the user's device).
In this deep systems engineering guide, we dissect the evolution of browser compute, contrast WebGL with WebGPU, explore WGSL (WebGPU Shading Language) compute shaders, analyze Tiled Shared Memory Matrix Multiplication ($GEMM$), and implement a runnable WebGPU tensor compute pipeline in JavaScript.
The Evolution of In-Browser High-Performance Computing
The journey from single-threaded JavaScript to massively parallel GPU computing spanned four architectural generations:
flowchart LR
    Gen1["1. Single-Threaded JS
(Scalar CPU execution, main event loop blocking)"] --> Gen2["2. Web Workers & asm.js
(Background threads, typed arrays)"]
    Gen2 --> Gen3["3. WebAssembly + 128-bit SIMD
(Near-native CPU instructions, 4x float parallel)"]
    Gen3 --> Gen4["4. WebGPU Compute Pipelines
(Direct GPU shader workgroups, TFLOPS tensor compute)"]

    style Gen1 fill:#475569,stroke:#94a3b8,color:#fff
    style Gen2 fill:#0284c7,stroke:#38bdf8,color:#fff
    style Gen3 fill:#7c3aed,stroke:#c084fc,color:#fff
    style Gen4 fill:#059669,stroke:#6ee7b7,color:#fff
Why WebGL Was Inadequate for General-Purpose Compute (GPGPU)
Before WebGPU, developers attempted to run neural networks in browsers using WebGL. However, WebGL was designed strictly for 3D rasterization rendering, forcing developers into grotesque architectural hacks:
- Float-to-Pixel Packing: Floats had to be encoded into RGBA pixel color channels of 2D textures.
- Fragment Shader Rendering: Tensor operations had to be disguised as draw calls rendering invisible rectangles onto off-screen framebuffers.
- No Inter-Thread Communication: WebGL fragment shaders cannot share memory or synchronize with neighboring threads in a threadblock.
WebGPU eliminates graphics baggage entirely by introducing dedicated Compute Passes, general-purpose Storage Buffers, and explicit Workgroup Local Memory.
WebGPU Architecture Internals: The Compute Pipeline
WebGPU maps directly to modern low-level native graphics and compute APIs (Vulkan on Linux/Android, DirectX 12 on Windows, and Metal on macOS/iOS):
flowchart TD
    subgraph Host Application (JavaScript / TypeScript)
        Adapter[GPU Adapter] --> Device[GPU Device (Logical handle)]
        Device --> BufferA["Input Storage Buffer A (Matrix A)"]
        Device --> BufferB["Input Storage Buffer B (Matrix B)"]
        Device --> BufferOut["Output Storage Buffer C (Matrix C)"]
        Device --> Pipeline["Compute Pipeline (Compiled WGSL Shader)"]

        BindGroup["Bind Group (Binds Buffers 0, 1, 2 to Shader slots)"]
        CommandEncoder["Command Encoder -> Compute Pass"]
    end

    subgraph Hardware GPU Execution Grid
        WorkgroupGrid["Dispatch Workgroups: (N/16, M/16, 1)"]
        WorkgroupGrid --> WG1["Workgroup (16x16 Invocations = 256 GPU Threads)"]
        WG1 --> LocalMem["Shared Workgroup Memory (SRAM)"]
        WG1 --> ALU["Tensor Matrix Arithmetic (GEMM)"]
    end

    Pipeline --> CommandEncoder
    BindGroup --> CommandEncoder
    CommandEncoder -->|queue.submit()| WorkgroupGrid

    style Device fill:#0284c7,stroke:#38bdf8,color:#fff
    style Pipeline fill:#7c3aed,stroke:#c084fc,color:#fff
    style WorkgroupGrid fill:#059669,stroke:#6ee7b7,color:#fff
    style LocalMem fill:#f59e0b,stroke:#fcd34d,color:#fff
Core WebGPU Primitives
GPUAdapter&GPUDevice: The adapter represents physical hardware (e.g. NVIDIA RTX 4090 or Apple M-series GPU); the device provides the programmatic interface to allocate memory and dispatch kernels.- Storage Buffers (
GPUBuffer): Flat, raw byte arrays in GPU memory mapped with specific usage flags (GPUBufferUsage.STORAGE | GPUBufferUsage.COPY_SRC). - Bind Groups (
GPUBindGroup): Pointers connecting storage buffers in host RAM to specific resource binding indices inside the WGSL shader. - Compute Pass & Dispatch: Enqueues shader execution across a 3D grid of workgroups:
passEncoder.dispatchWorkgroups(workgroupsX, workgroupsY, 1).
WGSL Deep Dive: Tiled Shared-Memory Matrix Multiplication ($GEMM$)
In Large Language Models and Deep Neural Networks, over 90% of compute time is spent executing General Matrix Multiplication ($GEMM$: $C = A \times B$).
A naive matrix multiplication kernel fetches numbers from global GPU VRAM on every iteration, saturating memory bandwidth. In WebGPU, high-performance engines use Tiled Matrix Multiplication leveraging fast Workgroup Shared Memory (var<workgroup>):
// WGSL (WebGPU Shading Language) Tiled GEMM Compute Shader
const BLOCK_SIZE: u32 = 16u;

struct MatrixDimensions {
    M: u32,
    K: u32,
    N: u32,
};

@group(0) @binding(0) var dims: MatrixDimensions;
@group(0) @binding(1) var matrixA: array;
@group(0) @binding(2) var matrixB: array;
@group(0) @binding(3) var matrixC: array;

// Workgroup Shared Memory (Fast on-chip SRAM cache)
var tileA: array, 16>;
var tileB: array, 16>;

@compute @workgroup_size(16, 16, 1)
fn main(
    @builtin(global_invocation_id) global_id: vec3,
    @builtin(local_invocation_id) local_id: vec3,
    @builtin(workgroup_id) group_id: vec3
) {
    let row = global_id.y;
    let col = global_id.x;
    var sum: f32 = 0.0;

    let numTiles = (dims.K + BLOCK_SIZE - 1u) / BLOCK_SIZE;

    // Loop through tiles of dimension K x K
    for (var t = 0u; t < numTiles; t = t + 1u) {
        // 1. Cooperatively load tiles from slow global VRAM into fast Shared SRAM
        let tiledColA = t * BLOCK_SIZE + local_id.x;
        let tiledRowB = t * BLOCK_SIZE + local_id.y;

        if (row < dims.M && tiledColA < dims.K) {
            tileA[local_id.y][local_id.x] = matrixA[row * dims.K + tiledColA];
        } else {
            tileA[local_id.y][local_id.x] = 0.0;
        }

        if (tiledRowB < dims.K && col < dims.N) {
            tileB[local_id.y][local_id.x] = matrixB[tiledRowB * dims.N + col];
        } else {
            tileB[local_id.y][local_id.x] = 0.0;
        }

        // Synchronize all 256 threads in workgroup before computing
        workgroupBarrier();

        // 2. Compute partial dot product from fast on-chip tile
        for (var k = 0u; k < BLOCK_SIZE; k = k + 1u) {
            sum = sum + tileA[local_id.y][k] * tileB[k][local_id.x];
        }

        // Synchronize before loading next tile
        workgroupBarrier();
    }

    // 3. Write final result to output buffer
    if (row < dims.M && col < dims.N) {
        matrixC[row * dims.N + col] = sum;
    }
}
By loading $16 \times 16$ chunks into shared memory, every byte read from global VRAM is reused 16 times across the workgroup, multiplying memory throughput by 16x!
WebAssembly 128-bit SIMD: The CPU Accelerator
While WebGPU is ideal for massive parallel matrix operations, WebAssembly with 128-bit SIMD (Single Instruction, Multiple Data) is optimal for serial token sampling, activation functions (GeLU / Softmax), and tokenizers.
Wasm SIMD provides v128 vector types capable of processing four 32-bit floats simultaneously in a single CPU instruction:
flowchart LR
    subgraph Wasm 128-bit SIMD Vector Operation
        V1["Vector A: [f32, f32, f32, f32] (128 bits)"]
        V2["Vector B: [f32, f32, f32, f32] (128 bits)"]
        FMA["f32x4.fma (Fused Multiply-Add)"]
        VOut["Vector C: [a0*b0+c0, a1*b1+c1, a2*b2+c2, a3*b3+c3]"]

        V1 --> FMA
        V2 --> FMA
        FMA --> VOut
    end

    style V1 fill:#0284c7,stroke:#38bdf8,color:#fff
    style V2 fill:#0284c7,stroke:#38bdf8,color:#fff
    style FMA fill:#7c3aed,stroke:#c084fc,color:#fff
    style VOut fill:#059669,stroke:#6ee7b7,color:#fff
Modern browser AI frameworks (like ONNX Runtime Web and Transformers.js) employ a hybrid architecture: WebGPU for large tensor matrix multiplication and Wasm SIMD for embedding lookups and tokenization.
Hands-On JavaScript Implementation: Complete WebGPU Compute Pipeline
Here is a complete, runnable modern JavaScript script setting up a WebGPU device, allocating tensor buffers, compiling a compute shader, and reading back results:
async function runWebGPUCompute() {
    // 1. Initialize GPU Adapter and Device
    if (!navigator.gpu) {
        throw new Error("WebGPU is not supported in this browser!");
    }
    const adapter = await navigator.gpu.requestAdapter();
    const device = await adapter.requestDevice();

    const M = 4, K = 4, N = 4;
    // Input Matrices (4x4 floats)
    const dataA = new Float32Array([
        1, 2, 3, 4,
        5, 6, 7, 8,
        9, 1, 2, 3,
        4, 5, 6, 7
    ]);
    const dataB = new Float32Array([
        1, 0, 0, 0,
        0, 1, 0, 0,
        0, 0, 1, 0,
        0, 0, 0, 1 // Identity matrix
    ]);

    // 2. Allocate GPU Buffers
    const bufferA = device.createBuffer({
        size: dataA.byteLength,
        usage: GPUBufferUsage.STORAGE | GPUBufferUsage.COPY_DST,
        mappedAtCreation: true,
    });
    new Float32Array(bufferA.getMappedRange()).set(dataA);
    bufferA.unmap();

    const bufferB = device.createBuffer({
        size: dataB.byteLength,
        usage: GPUBufferUsage.STORAGE | GPUBufferUsage.COPY_DST,
        mappedAtCreation: true,
    });
    new Float32Array(bufferB.getMappedRange()).set(dataB);
    bufferB.unmap();

    const resultBufferSize = M * N * Float32Array.BYTES_PER_ELEMENT;
    const bufferC = device.createBuffer({
        size: resultBufferSize,
        usage: GPUBufferUsage.STORAGE | GPUBufferUsage.COPY_SRC,
    });

    // Readback staging buffer for CPU access
    const readbackBuffer = device.createBuffer({
        size: resultBufferSize,
        usage: GPUBufferUsage.MAP_READ | GPUBufferUsage.COPY_DST,
    });

    // 3. Compile WGSL Shader Module
    const shaderModule = device.createShaderModule({
        code: `
        @group(0) @binding(0) var A: array;
        @group(0) @binding(1) var B: array;
        @group(0) @binding(2) var C: array;

        @compute @workgroup_size(4, 4)
        fn main(@builtin(global_invocation_id) id: vec3) {
            let row = id.y;
            let col = id.x;
            var sum = 0.0;
            for (var k = 0u; k < 4u; k = k + 1u) {
                sum = sum + A[row * 4u + k] * B[k * 4u + col];
            }
            C[row * 4u + col] = sum;
        }
        `
    });

    // 4. Create Compute Pipeline & Bind Group
    const pipeline = device.createComputePipeline({
        layout: 'auto',
        compute: { module: shaderModule, entryPoint: 'main' },
    });

    const bindGroup = device.createBindGroup({
        layout: pipeline.getBindGroupLayout(0),
        entries: [
            { binding: 0, resource: { buffer: bufferA } },
            { binding: 1, resource: { buffer: bufferB } },
            { binding: 2, resource: { buffer: bufferC } },
        ],
    });

    // 5. Encode and Submit GPU Commands
    const encoder = device.createCommandEncoder();
    const pass = encoder.beginComputePass();
    pass.setPipeline(pipeline);
    pass.setBindGroup(0, bindGroup);
    pass.dispatchWorkgroups(1, 1);
    pass.end();

    // Copy GPU result buffer to readable CPU staging buffer
    encoder.copyBufferToBuffer(bufferC, 0, readbackBuffer, 0, resultBufferSize);
    device.queue.submit([encoder.finish()]);

    // 6. Map and Read Results Back to CPU
    await readbackBuffer.mapAsync(GPUMapMode.READ);
    const resultArray = new Float32Array(readbackBuffer.getMappedRange());
    console.log("Computed Matrix C Result on WebGPU:");
    console.log(Array.from(resultArray));
    readbackBuffer.unmap();
}
Production Comparison: Browser Compute Paradigms
| Technology | Execution Hardware | Parallel Concurrency | Throughput Scale (GFLOPS) | Primary Use Case |
|---|---|---|---|---|
| Standard JavaScript | Single CPU Thread | 1 Thread (Event Loop) | ~1 – 5 GFLOPS | DOM manipulation, API orchestration |
| WebAssembly (Wasm) | Multi-Core CPU | 1 – 16 CPU Threads | ~20 – 50 GFLOPS | Codecs, compression, game logic |
| Wasm 128-bit SIMD | CPU SIMD (AVX / NEON) | 4x Floats per instruction | ~80 – 200 GFLOPS | Tokenizers, audio DSP, embedding search |
| WebGPU Compute | Native GPU Cores | Thousands of parallel shader workgroups | 1,000 – 15,000+ GFLOPS (TFLOPS) | Local LLM inference, Stable Diffusion, Computer Vision |
Summary & Architectural Insights
- The Browser is a First-Class Compute Platform: WebGPU unlocks direct access to client graphics silicon, delivering 100x speedups over pure JavaScript.
- Zero-Cost Scalability: Running AI model inference in client browsers eliminates expensive backend GPU server hosting bills while protecting user privacy.
- Shared Memory is Essential for Matrix Operations: Tiled WGSL algorithms utilizing
var<workgroup>SRAM buffers dramatically reduce memory bus saturation during tensor arithmetic. - Hybrid CPU/GPU Architecture Wins: Combine WebAssembly SIMD for low-latency pre-processing and tokenization with WebGPU compute pipelines for heavy matrix multiplication.