#Developer Tools
Sep 13, 2026
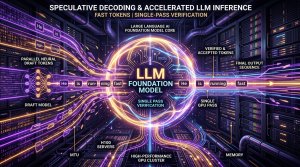
Speculative Decoding in Production: Accelerating LLM Inference 3x with Medusa Heads, Draft Models, and Verification Kernels
A deep architectural guide to Speculative Decoding in LLM inference: why memory bandwidth creates an autoregressive bottleneck, draft-and-verify execution pipelines, multi-head Medusa architectures, tree-based attention verification, and deploying in vLLM.